Low Rank Tensor Recovery for Joint Probability Distribution
Tensors
- A scalar can be represented by a single component with zero basis vectors for each component.
- A vector of 3 dimensions can be specified using three components and one basis vector for each component.
- A stress matrix can be represented by nine components (we are considering 3 dimensions). That is two basis vectors for each component.
All of the above mathematical objects fall under a broad class of Tensors.
Tensors: In an -dimensional space, a tensor of order has indices and components in a chosen basis, with components that obey the tensor transformation rules.
Generally, in real-life scenarios. is used while discussing relativity.
CP rank is the minimum number of rank- tensors whose sum equals the tensor.
Transformation rules of tensors
- A tensor is an object that transforms like a tensor
- A tensor is an object that is an object that is invariant under a change of coordinate system with components that change according to a special set of mathematical formulae
In simpler terms, the actual tensor is invariant to a change in the coordinate systems. For example, the displacement vector pointing from to ( a rank tensor) does not change when coordinates change. The vector will still be pointing from to . However, the way we represent the vector, i.e., the components changes.
Matrices Tensors
Matrices are a form of representation of rank- tensors. They are just an array of numbers. Although, Tensors require detailed specification and are invariant under change of coordinate systems.
Einstein Notation for Tensors
Both subscripts and superscripts are used for indices in tensors.
-
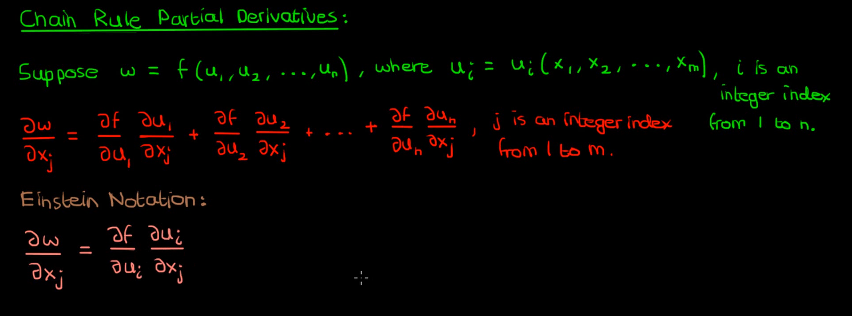
Any twice repeated index in a single term is summed over. Index . Typically,
For example,
Here, is a dummy variable and is a free variable.
Dummy indices can be replaced, whereas free indices can’t be. A free index takes only one value in an expression.
-
No index may occur or more times in a given term.
We count subscripts and superscripts together. That is,
- is a dummy variable
-
In an equation involving Einstein notation, the free indices on both sides must match.
Brackets in Einstein Notation
- Combine terms outside parentheses with each term inside parentheses separately.
- From each of the combined terms, use the largest count of each index as the final count in the overall term.
Kronecker Delta
Linear algebra of Tensors
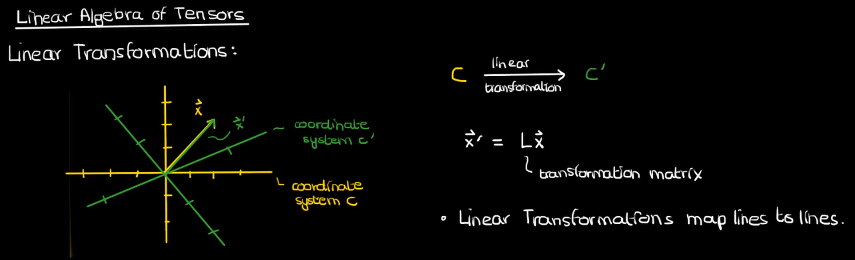
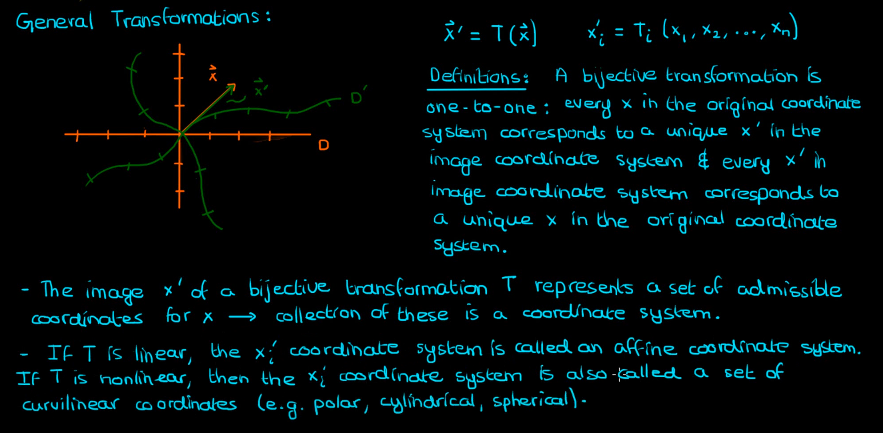
For the following analysis, we shall be using the superscript notation to denote each element of a vector.
Rectangular coordinate system - A coordinate system () in is rectangular if the distance between points and is given by :
Curvilinear coordinates
- is a point in a coordinate system () in given by
- is another coordinate system in such that the coordinates of in this system are
- Suppose that . If the functions are all real valued, have continuous nd partial derivatives everywhere, and are all invertible then is called a coordinate transformation.
The Jacobian is non-zero over a region in iff the corresponding transformation is locally bijective in that region .
The Jacobian matrix of the inverse transformation is the inverse of the Jacobian matrix of
The above was taken from here
Recovering Joint Probability of Discrete Random Variables from Pairwise Marginals
Tensor Algebra
Canonical Polyadic Decomposition
If an -way tensor has Canonical Polyadic rank , it can be written as
where is called the mode- latent factor. In the above, with is employed to ‘absorb’ the norms of columns.
In other words an -way tensor representing the joint PMF of discrete RVs where , admits a CPD if it can be decomposed as a sum of rank- tensors. Denoting as the outer-product (Kronecker Product) of two vectors, the CPD model is:
Here, is the rank of the tensor.
Joint PMF Recovery: A Tensor Perspective
Any joint PMF admits a naive Bayes (NB) model representation; i.e., any joint PMF can be generated from a latent variable model with just one hidden variable. It follows that the joint PMF of can always be decomposed as: