Numerical Analysis
Contents
- Aspects of numerical analysis
- Finite digit arithmetic
- Floating-point representation
- Errors
- Significant digits
- Finite Digit Arithmetic
- Major sources of errors
- Can we avoid errors?
- Roots of equations
- Fixed points and roots
- Newton-Raphson method
- Secant method
- The method of false position
- Comparison of all the root finding methods
- Order of convergence
- Multiplicity of a zero
- Order of the fixed point iteration method
- Modified Newton-Raphson
- An other methods?
- Taylor polynomials
- Lagrange interpolating polynomials
- Uniqueness of the interpolating polynomial
- Error of the interpolating polynomial
- Neville’s formula
- Divided Differences
Lecture 1
Numerical Analysis is the study of various methods
- to solve
- differential equations,
- systems of linear equations,
- .
- to approximate functions and
- to study the corresponding errors.
Example. . How do we approximate to an arbitrary accuracy? Since, the function is infinitely many times differentiable, we can approximate the function using Taylor's theorem to any degree of precision we want.
For example, suppose we want the error to be less than , then we use .
Note. The last term is not the error in our approximation! We are choosing for no particular reason. It can be any value greater than the true value of . For instance, we can take too. If we want our calculated value value to be precise till the 10th decimal, then we ensure that by tuning appropriately.
Aspects of numerical analysis
- The theory behind the calculation, and
- The computation.
Some calculators have a loss of information due to limits in precision. This is due to the round-off error. We need to be able to detect and deal with such cases.
Lecture 2
Finite digit arithmetic
When we do arithmetic, we allow for infinitely many digits. However, in the computational world, each representable number has only a fixed and finite number of digits. In most cases, the machine arithmetic is satisfactory, but at times problems arise because of this discrepancy. The error that is produced due to this issue is called the round-off error.
A 64-bit representation is used for a real number. The first bit is a sign indicator, denoted by s. This is followed by an 11-bit exponent, c, called the characteristic, and a 52-bit binary fraction, f, called the mantissa. To ensure that numbers with small magnitude are equally representable, 1023 is subtracted from the characteristic, so the range of the normal exponent is actually from -1022 to 1023.
Thus, the system gives a floating-point number of the form
Can't a single number be represented in many ways through this representation? Think about 1 for instance.
The smallest positive number that can be represented is with , so it is
The largest positive number is
Floating-point representation
We will use numbers of the form
- Chopping. We simply chop off the and write
- Rounding. We add to the number and then chop the result to obtain
Errors
This approximate way of writing numbers is bound to create errors. If is a real number and if is its approximation then the absolute error is while the relative error is whenever . Relative error is more meaningful as it takes into account the size of the number .
Note. Relative error is nonnegative because both the numerator and denominator use absolute values.
Significant digits
We say that the number approximates to significant digits if is the largest non-negative integer for which
Finite Digit Arithmetic
The arithmetic in machines in defined by the following -
Lecture 3
Major sources of errors
One of the major sources of errors is cancellation of two nearly equal numbers. Suppose we have
Another way the errors creep in is when we divide by number of small magnitude or multiply by numbers of large magnitude. This is because the error gets multiplied by a factor which increases its absolute value.
Consider the expression . By default, we consider positive square roots. Here, if is large compared to then the machine is likely to treat as zero. How do we get around this error? Rationalization
Notice what happened here. Previously, the roots would have become zero because could have been approximated as zero. However, this does not happen after rationalization! Also, do note that this won’t work when as we are considering positive square roots. If , we can use the formula without rationalization. Think about the other root using such cases. Thus, the cancellation error can come in two major ways:
- when we cancel two nearly equal numbers, and
- when we subtract a small number from a big number
Errors propagate
Once an error is introduced in a calculation, any further operation is likely to contain the same or a higher error.
Can we avoid errors?
Errors are inevitable in finite arithmetic. There are some measures that we can take to try to avoid errors, or minimize them. For example, a general degree 3 polynomial can be written as a nested polynomial.
Lecture 4
Roots of equations
The zeros of a function can give us a lot of information regarding the function. Why specifically zero? Division is in general more difficult to implement in comparison to multiplication. Division is implemented via the solution to roots of an equation in computers. There are other reasons such as eigenvalue decomposition. We shall see all of this later in the course.
Theorem. Intermediate Value Theorem. If is a continuous function with then there is a such that .
Bisection method
The bisection method is implemented using the above theorem. To begin, we set and , and let be the midpoint of ;
- If , then we are done
- If , then the subinterval contains a root of , we then set and
- If , then the subinterval contains a root of , we then set and
We continue this process until we obtain the root. Each iteration reduces the size of the interval by half. Therefore, it is beneficial to choose a small interval in the beginning. The sequence of is a Cauchy sequence. IT may happen that none of the is a root. For instance, the root may be an irrational number and may be rational numbers. There are three criteria to decide to stop the bisection process.
- - not very good because it may take a long time to achieve it, or that it may be achieved easily and yet is significantly many steps away from a root of
- is not good because it does not take the function into account. While and may be close enough but the actual root may still be many steps away.
- looks enticing as it mimics the relative error but again it does not take into account.
The bisection method has significant drawbacks - It is relatively slow to converge, and a good intermediate approximation might be inadvertently discarded. However, the method has the important property that is always converges to a solution.
Lecture 5
Fixed points and roots
A fixed point of is such that . Finding a fixed point of the function is equivalent to finding the root of the function . We can create many such functions which give fixed points of on solving for the roots of the function.
Theorem. Fixed Point Theorem. If is continuous then has a fixed point. If, in addition, exists on and for all then has a unique fixed point in .
The hypothesis is sufficient but not necessary!
Fixed point iteration
We start with a continuous . Take any initial approximation and generate a sequence . If the sequence converges to then
For instance, consider the roots of the equation . The following functions can be used to find the roots using the fixed points.
So now we have the question - How can we find a fixed point problem that produces a sequence that reliably and rapidly converges to a solution to a given root-finding problem?
Lecture 6
Newton-Raphson method
This is a particular fixed point iteration method. Assume that is twice differentiable. Let be a solution of the equation . If is another point in then Taylor’s theorem gives
for some between and . We assume that is very small. Therefore, . This sets the stage for the Newton-Raphson method, which starts with an initial approximation and generate the sequence by
What is the geometric interpretation of this method? It approximates successive tangents. The Newton-Raphson method is evidently better than the fixed point iteration method. However, it is important to note that is need to be small so the third term in the Taylor’s polynomial can be dropped.
Theorem. Let be twice differentiable. If is such that and , then there exists a such that for any , the Newton-Raphson method generates a sequence converging to .
This theorem is seldom applied in practice, as it does not tell us how to determine the constant . In a practical application, an initial approximation is selected and successive approximations are generated by the method. These will generally either converge quickly to the root, or it will be clear that convergence is unlikely.
Lecture 7
Problems with the Newton-Raphson method
We have
One major problem with this is that we need to compute the value of at each step. Typically, is far more difficult to compute and needs more arithmetic operations to calculate than .
Secant method
This method is a slight variation to NR to circumvent the above problem. By definition,
If we assume that is reasonable close to then
This adjustment is called as the secant method. The geometric interpretation is that we use successive secants instead of tangents. Note that we can use the values of from the previous calculations to prevent redundant steps. We need two initial guesses in this method.
Secant method is efficient in comparison to Newton-Raphson as it requires only a single calculation in each iteration whereas NR requires 2 calculations in each step.
The method of false position
The NR or the Secant method may give successive approximations which are on one side of the root. That is need not be negative. We can modify this by taking the pair of approximations which are on both sides of the root. This gives the regula falso method or the method of false position.
We choose initial approximations and with . We then use Secant method for successive updates. If in any iteration, we have , then we replace by .
The added requirement of the regula falsi method results in more calculations than the Secant method.
Comparison of all the root finding methods
- The bisection method guarantees a sequence converging to the root but it is a slow method.
- The other methods are sure to work, once the sequence is convergent. The convergence typically depends on the initial approximations being very close to the root.
- Therefore, in general, bisection method is used to get the initial guess, and then NR or the Secant method is used to get the exact root.
Lecture 8
We are reaching the end of the equations in one variable theme.
Order of convergence
Let be a sequence that converges to with for any . If there are positive constants and such that
then the order of convergence of to is with asymptomatic error . An iterative technique of the form is said to be of order if the sequence converges to the solution with order .
In general, a sequence with a high order of convergence converges more rapidly than a sequence with a lower order. The asymptotic constant affects the speed of convergence but not to the extent of the order.
Two cases of order are given special attention
- If and , the sequence is linearly convergent.
- If , the sequence is quadratically convergent.
Order of convergence of fixed point iteration method?
Consider the fixed point iteration . The Mean Value Theorem gives
where lies between and , hence . Therefore,
The convergence of a fixed point iteration method is thus linear if and .
We need to have for a higher order of convergence.
why?
Theorem. Let be a solution of the equation . Let and be continuous with nearby . Then there exists a such that, for , the sequence defined converges at least quadratically to . Moreover, for sufficiently large values of
For quadratically convergent fixed point methods, we should search for functions whose derivatives are zero at the fixed point. If we have the root-finding problem for , then the easiest way to construct a fixed-point problem would be
where is a differentiable function, to be chosen later. Therefore, define which gives
This is the Newton-Raphson method! We have assumed that in the above analysis; if this assumption fails, the quadratic-convergence result need not hold.
Multiplicity of a zero
Let be a function and let be a zero of . We say that is a zero of multiplicity of if for , we can write with .
Whenever has a simple zero () at , then the NR method works well for . However, NR does not give a quadratic convergence if the order of the zero is more than 1.
Lecture 9
Note. -digit arithmetic deals with significant digits and not places after the decimal.
Order of the fixed point iteration method
Summarizing the last lecture we have
- If we have a function whose roots are to be found, we can convert it to a fixed point problem by appropriately constructing a .
- If we construct such that it’s derivative is non-zero at the root, then the fixed point iteration method is linear.
- Otherwise, if the derivative is zero, then the fixed point iteration method is quadratic or higher. For example, we constructed such a which mirrored the Newton-Raphson method.
- In the Newton-Raphson method itself, if the root is a simple zero of , the method has quadratic convergence. However, if it is not a simple zero if then the method may not have a quadratic convergence.
Can we modify NR to overcome the limitation of multiplicity of the zero?
Modified Newton-Raphson
For a given , we define a function
If is a xero of with multiplicity , we have
Notice that is a simple root of . Further, assume are continuous. Then, if has no other zero in a neighborhood of then will also not have any other zero in that neighborhood. We can now apply Newton-Raphson method to .
The fixed point iteration is given by
This iteration will converge to with at least the quadratic order of convergence. The only theoretical drawback with this method is that we now need to compute at each step. Computationally, the denominator of the formula involves cancelling two nearly equal terms ( is a root of both ).
Note that if is a simple zero, the modified Newton-Raphson still bodes well. It’s just that there are a lot more calculations in the modified NR method.
An other methods?
There are many methods other than the 4 we considered so far. Suppose that converges to linearly. For large enough , we have which further gives
This is called Aitken’s -method of accelerating convergence. So, if we have a sequence converging to linearly, we can come up with an alternate sequence using the original sequence that converges faster.
This brings us to the end of the second theme of our course - Equations in one variable.
Lecture 10
We begin the third theme of our course - Interpolation
Polynomials are very well studied functions. They have the form . Given any continuous function , there exists a polynomial that approximates the given function uniformly on as closely as desired. This is known as the Weierstrass approximation theorem. Another reason to prefer polynomials is that the derivatives of polynomials are also polynomials.
Taylor polynomials
We can consider the polynomials formed by Taylor’s theorem. However, these polynomials approximate the function only at a single point. The advantage of using these polynomials is that the error between the function and the polynomial can be determined accurately. For ordinary computational purposes it is more efficient to use methods that include information at various points.
Lagrange interpolating polynomials
Let be a function with . Is there a polynomial with .
The simplest case is . If we have two points and , then we can have . We can generalize this for more number of points.
Let be distinct points and let be a function with for . We want to find a polynomial that equals at these points. To do this, we first solve special problems, using for each fixed . We find polynomials with
For a fixed , for . So divides for each . Since the points are all distinct, we have that the product of all such ‘s divides . We define as
then . Now, can be constructed as
The validity of this polynomial can be checked easily.
Lecture 11
What if you take a linear function and use points for Lagrange interpolation? Will the final function be linear? It should be.
For example, in class we considered and . These values gave a constant polynomial.
In general, for -points, the interpolating polynomial will have degree at most .
Uniqueness of the interpolating polynomial
For a given set of points, we can have infinitely many polynomials which interpolate it. However, there exists a unique polynomial with degree . This result follows from the well-known theorem -
Theorem. A polynomial of degree has at most distinct zeroes.
Corollary. A polynomial with degree with zeroes is the zero polynomial.
Error of the interpolating polynomial
Theorem. Let be -times continuously differentiable. Let be the polynomial interpolating at distinct points . Then, for each , there exists with
How? Intuition?
Using the above theorem, we can calculate the maximum possible value of the absolute error in an interval.
Note. While checking for extreme values in an interval, do not forget to check the value of the function at the edge of the interval!
Lecture 12
Note. The value of for the error calculation depends on the point at which error is being calculated.
Practical difficulties with Lagrange Polynomials
To use the error form, we need some information about in order to find its derivative. However, this is often not the case. Also, the computations of the lower degree interpolating polynomials does not quite help the computations of the higher degree ones. We would like to find a method that helps in computing the interpolating polynomials cumulatively.
Cumulative calculation of interpolating polynomials
Let us assume that is given on distinct nodes . Now, the constant polynomial for the node will be and that for the node will be . Using Lagrange interpolation, we have
Can we generalize this? Let us try to construct the quadratic polynomial. Now, suppose we have and $Q_1(x)$. The quadratic polynomial for the nodes is given by,
We shall see the general formula in the next lecture.
Lecture 13
Before we move on to the general formula, let us take the previous calculations one step further. Suppose we had to calculate the cubic polynomial in terms of the quadratic polynomials. The tedious way to do this is to expand each formula and substitute. We also have an easy way to do this. Recall the ‘unique polynomial’ theorem from last week. If we guess the formula of the cubic polynomial using induction, then all we have to do is check the value of the function at the 4 points which define it. If the value matches, then it is the polynomial we are looking for due to uniqueness.
Neville’s formula
Let be defined on . Choose two distinct nodes and . Let be the polynomial interpolating on all nodes except , and let be the one interpolating on all nodes except . If denotes the polynomial interpolating on all notes then
In Neville’s formula we can get the interpolating for higher degree from any two polynomials for two subsets of nodes which are obtained by removing a single node. Through such cumulative calculations, we can calculate the interpolating polynomials up to a certain degree until we get the required accuracy. Neville’s method gives the values of the interpolating polynomials at a specific point, without having to compute the polynomials themselves.
Divided Differences
Given the function on distinct nodes, there is a unique polynomial interpolating on these nodes. We define to be the coefficient of in . Now, it follows readily that the value of does not depend on the ordering of the nodes . Now, we shall try to get a recurrence formula for the coefficients .
Let and be the polynomials interpolating on the nodes and respectively. We can get from these two polynomials using Neville’s method. The coefficient of in is then
Also note that for . That is, where is a real number. Hence, and we have
This formula is known as Newton’s finite differences formula.
Lecture 14
We have
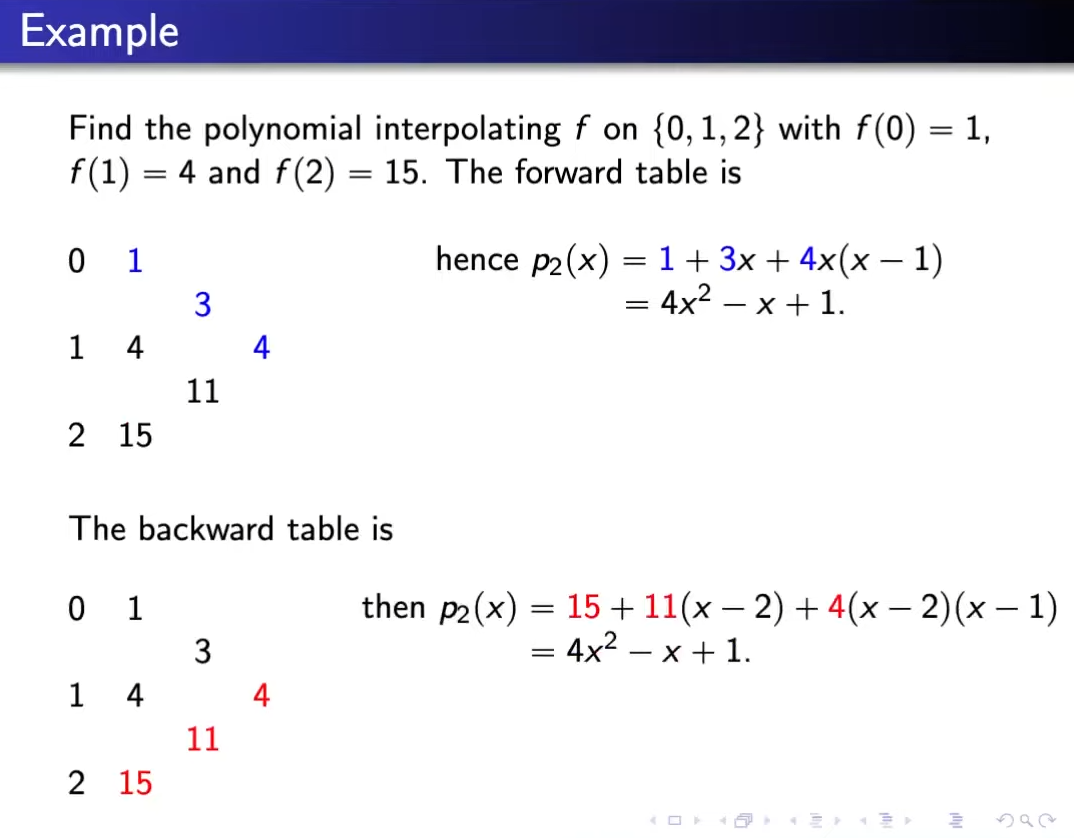
Since the order of the nodes does not matter, we can traverse the recursion in a forward/backward manner. The forward formula is given by,
The backward formula simply replaces by for . For clarity, look at the following example.
Nested form of the interpolating polynomial
Neste form of the interpolating polynomial is useful for computing the polynomials effectively.
Divided differences as a function
We now give a definition of the divided differences when some of the nodes may be equal to each other. By the Mean Value Theorem, for some between and . In fact, we also have the following theorem,
Theorem. If is -times continuously differentiable on then
for some .
Since for some between and , we define . Similarly, we define in a similar way using limits. For instance,
We have thus defined in general. Now, by letting the last as variable , we get a function of x: . This function is continuous.
MA214 post-midsem notes
-
Composite numerical integration - Newton-Cotes doesn’t work for large intervals. Therefore, we divide the interval into sub-parts. We are essentially doing a spline sorta thing instead of a higher degree polynomial.
-
Error in composite trapezoidal rule is , and in composite Simpson’s rule is .
-
The round-off error does not depend on the number of calculations in the composite methods. We get
Therefore, integration is stable.
-
Adaptive Quadrature method -
We will assume . Under this assumption, the two-subinterval composite Simpson estimate has about one-sixteenth the error of the one-panel estimate; the difference between those estimates is about 15 times the error in the two-subinterval estimate. If one of the subintervals has error more than , then we divide it even further.
Check this properly!
-
Gaussian Quadrature method -
Choose points for interval in an optimal way and not equally spaced. We choose and to minimise the error in
There are parameters, then the largest class of polynomials is the set of polynomials with degree for the approximation to be exact.
Note. Work with special cases of polynomials like to get the values of the coefficients easily. (because all polynomials in the set must satisfy the approximation)
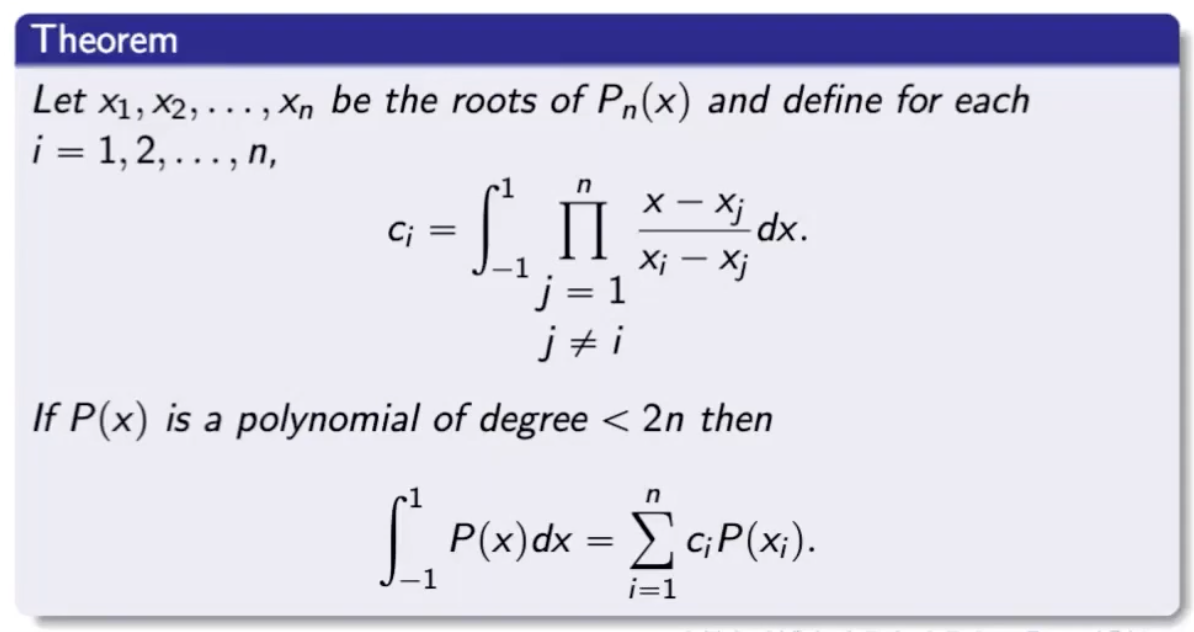
Legendre polynomials - There exist polynomials for satisfying
- is a monic polynomials
- whenever the degree of is less than .
For example, . can be computed from and as and are 0.
-
Multidimensional integrals - Composite trapezoidal rule has square of the number of function evaluations required for a single integral (for 2D).
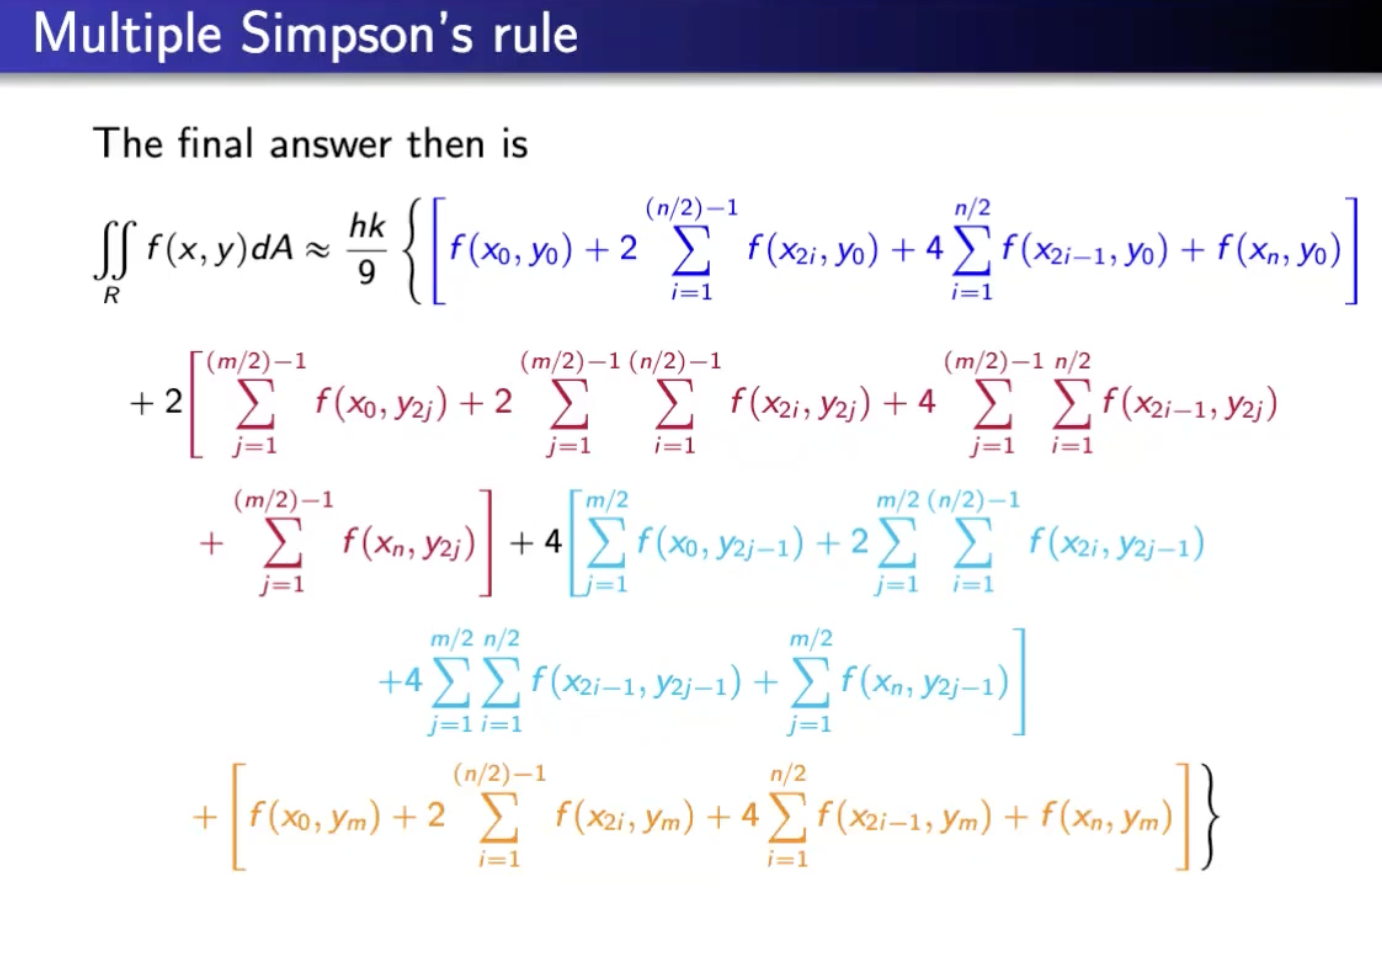
See if problems to be practiced here.
-
Improper integrals - Function is unbounded or the interval is unbounded. We will deal with functions where the function is unbounded on the left end.
-
Aside. is defined as in the complex domain. is not defined as the inverse of as is neither surjective (doesn’t take the value 0) nor injective (periodic in ). is defined by the power series and so is . The solution set of for where is given by
If where and is continuous then the improper integral exists. Assume is 5-times continuously differentiable. We can estimate the integral of using the following
- Get which is the 4th degree Taylor’s polynomial of .
- Get the exact value of .
- Get the value of the difference by defining the value at as using composite Simpson’s rule.
Why can’t we do Simpson’s on everything? That would lead to a similar thing. Think. Also, we require 4 times continuously differentiable for Simpson’s
The other type of improper integral involves infinite limits of integration. The basic integral is of the type for . Then, we substitute and proceed.
-
Ordinary Differential Equations We shall develop numerical methods to get solutions to ODEs at a given point. Then, we can use interpolation to get an approximate continuous solution.
A function is said to satisfy a Lipschitz condition in the variable on a set if a constant exists with
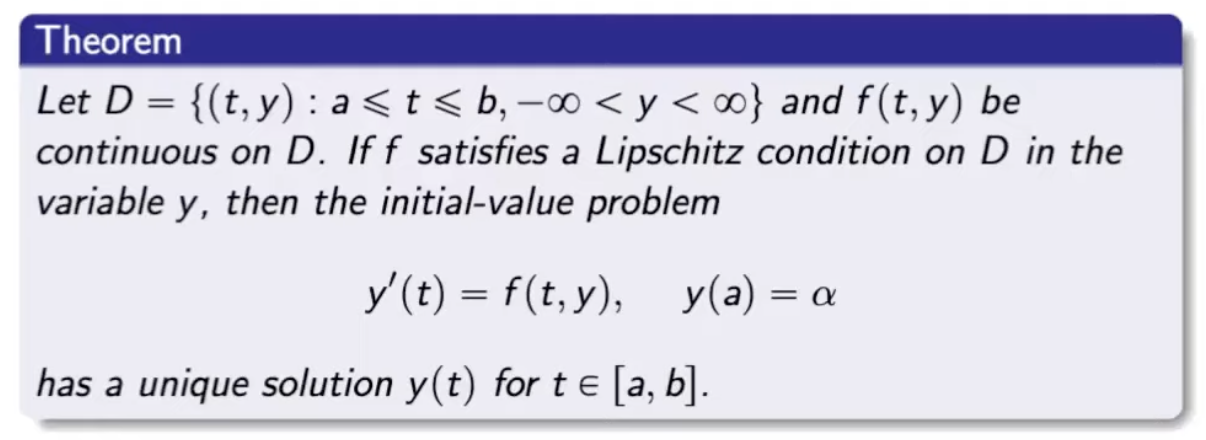
IVP is well-posed if it has a unique solutions, and an IVP obtained by small perturbations also has a unique solution. We consider IVPs of the form , , .
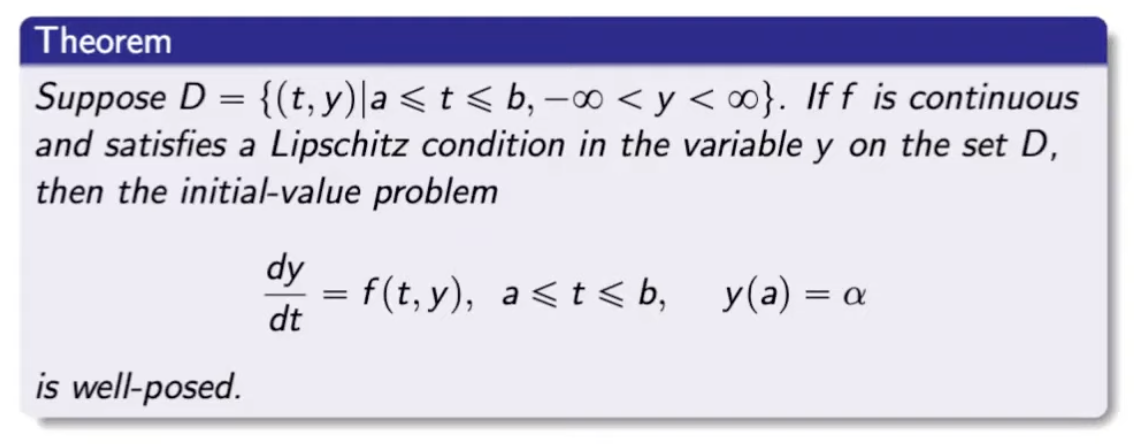
-
Euler’s method - We generate mesh points and interpolate. As we are considering IVPs of a certain form, we can just use 1st degree Taylor’s polynomial to approximate the solution to the IVP. We take and for where . The error grows as increases, but it is controlled due to the stability of Euler’s method. It grows in a linear manner wrt to .
-
Error in Euler’s method - Suppose , then . What about round-off errors? We’ll get an additional factor of in the above expression along with the constant . Therefore, .
-
Local truncation error - . It is just for Euler’s method ( refers to the Taylor polynomial). We want truncation error to be as for as large as possible.
Higher order Taylor methods - Assume is -times continuously differentiable. The local truncation error is for an th-degree Taylor polynomial. However, the number of computations are a bit high.
Practice problems on this
-
What about interpolation? We should use cubic Hermite interpolation (to match the derivative too).
-
Now, we try to reduce the computation of higher order derivatives. Runge-Kutta methods - Based off Taylor’s theorem in two variables.
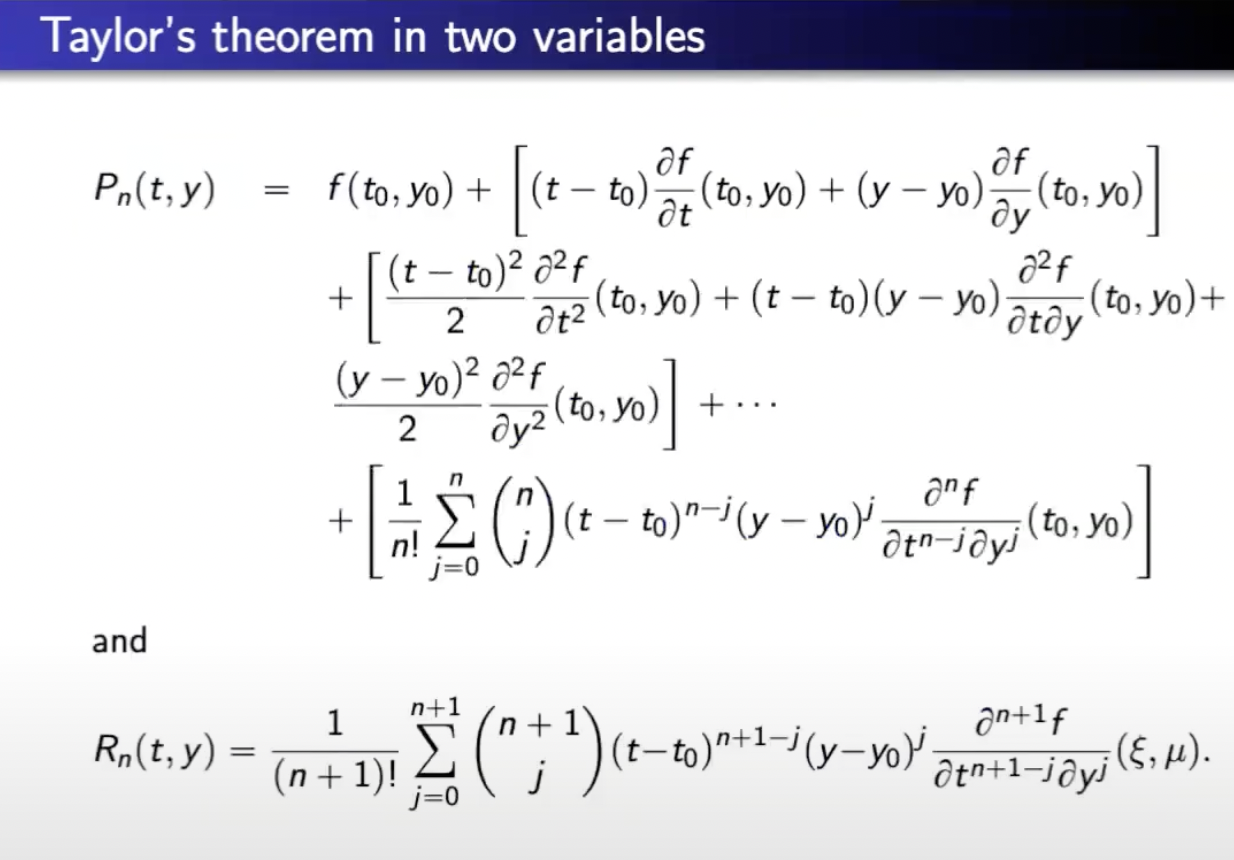
Order 2- We get by equating to . This specific Runge-Kutta method of Order 2 is known as the midpoint-method. (2D of Taylor order 2)
The number of nesting ‘s represents the order of the differential equation.
Suppose we try the form containing 4 parameters to approximate. We still get as there is only one nesting.
-
However, the flexibility in the parameters allows us to derive the Modified Euler method.
Higher-order Runge-Kutta methods - The parameter values are used in the Heun’s method.
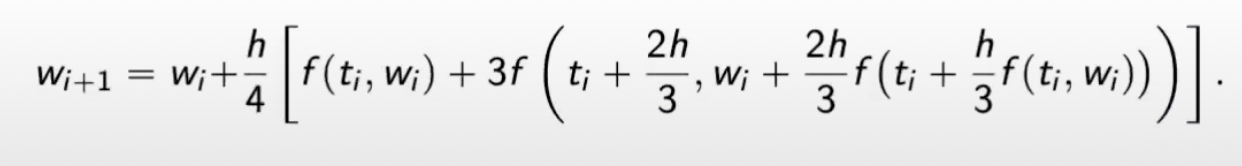
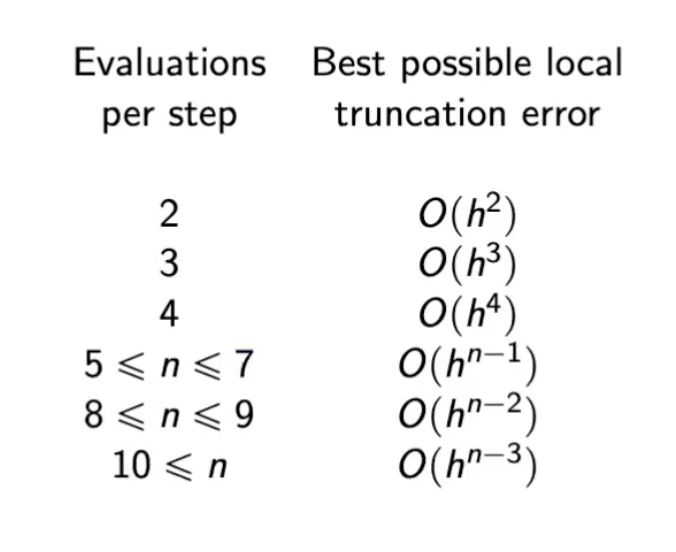
The most common Runge-Kutta method is order 4, with local truncation error under the normalized definition above.
-
Error control in Runge-Kutta methods. Adaptive step size for lower error. Single step approximation - uses for . Given an , we need to be able to give a method that gives .
Local truncation error assumes th measurement is correct to find error in the th measurement. We get
assuming . For th degree truncation error, we get . After a few approximations, we get that the local truncation error changes by a factor of when the step size changes by a factor of .
-
Runge-Kutta-Fehlberg Method - It uses a Runge-Kutta method with local truncation error of order five. We change the step size if . These methods are just an analogue of adaptive quadrature methods of integrals.
-
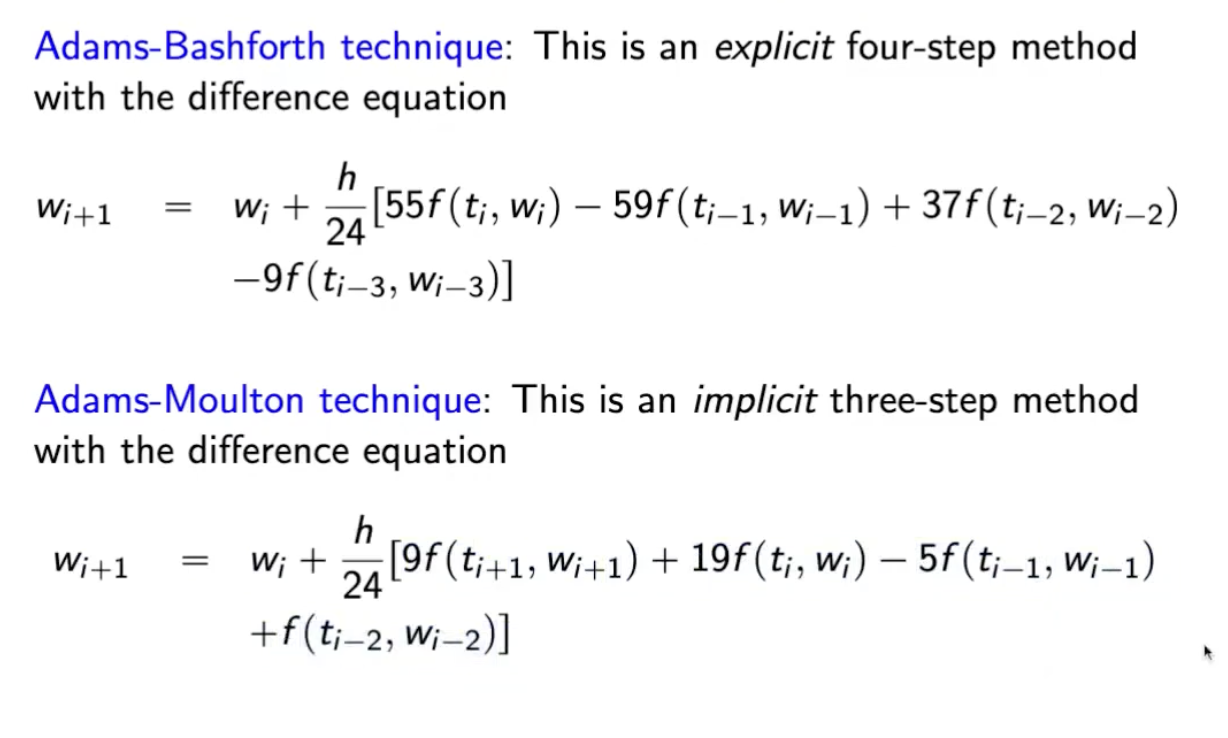
Multi-step methods. Methods that use the approximation at more than one previous mesh point to determine the approximation at the next point. The general equation is implicit where occurs on both sides of the equation. Implicit methods are more accurate than explicit methods.
-
Predictor-Corrector Method - How do we solve implicit methods? We can use the root-finding procedures we learnt. All of this can get quite cumbersome. We just use implicit methods to improve the prediction of the explicit methods. We insert the solution of explicit method (prediction) and insert it on the rhs of the implicit method (correction).
-
Consistency and Convergence
One-step difference method is consistent if . But we also need the global measure - convergence -
stability considering round-off errors. For the function satisfying Lipschitz condition with a , the one-step difference method is convergent iff it is consistent. The local truncation error is bounded, and we get .
Analysis of consistency, convergence, and stability is difficult for multi-step methods. Adams-* methods are stable.
-
Numerical Linear Algebra - Basics - has a unique solution iff is invertible, and it does not have a unique or has no solution otherwise.
Cramer’s rule - . However, this is cumbersome. Determinant of an upper triangular matrix is product of the diagonal entries.
Gaussian Elimination Method - for most matrices . is a lower triangular matrix and is an upper triangular matrix. Form the augmented matrix . Linear combination of rows and swapping of rows can be performed. What is the total number of arithmetic operations?
For converting to triangular - We use divisions for each row and multiplications for each column of each row. Also, we have subtractions. In total, we have multiplications. Summing, we get multiplications () and subtractions .
For back substitution - multiplication is and subtraction is .
-
We have not considered finite digit arithmetic for GEM previously. The error dominates the solution when the pivot has a low absolute value. In general, we need to ensure that the pivot does not have very low magnitude by interchanging rows (followed by interchanging columns for triangular form if needed) - partial pivoting. However, this might not be enough to get rid of the rounding error. Therefore, we need to consider scaled partial pivoting. Define as the maximum magnitude in the th row. Now, the first pivot is chosen by taking the row with the maximum value of . The operation count order still remains the same. You need not calculate scale factors more than once.
-
LU Decomposition - The conversion of to a triangular form using the above method can be represented as a sequence of matrix multiplications (if does not require any row interchanges). The inverse of a matrix depicting operations on can be seen a matrix depicting the same inverse operations on . In the end, we get where each represents the action that uses as a pivot. Once we get and , we can solve and separately. There are multiple decompositions possible which are eliminated by imposing conditions on the triangular matrices. A common normalization is to set the diagonal of one triangular factor to 1. For a symmetric positive-definite matrix, the Cholesky factorization is .
We had assumed that row interchanges are not allowed. However, we can build permutation matrices for row interchanges which will be of the form of an identity matrix with row permutations.
Therefore, we get PLU decomposition.
-
Diagonally dominant matrices - An matrix is said to be diagonally dominant when for all rows. A strongly diagonally dominant matrix is invertible. Such matrices will not need row interchanges, and the computations will be stable wrt the round off errors.
Why this instead of
A matrix is positive definite if for every . We shall also consider to be symmetric in the definition. Every positive definite matrix is invertible, for each , for , and .
A leading principal submatrix of matrix is the top-left submatrix of . is positive definite iff each leading principal submatrix of has a positive determinant.
For a symmetric positive-definite matrix, Gaussian elimination can proceed without row or column interchanges.
A matrix is positive definite iff where is lower triangular with 1’s on the diagonal and is a diagonal matrix with positive diagonal entries. Alternatively, is positive dfinite iff where is a lower triangular matrix. Note. Positive definite is stronger than Cholesky decomposition.
-
We have been seeing direct methods for solving . We shall see some iterative methods now. We need a distance metric to check the closeness of the approximation. We will consider distance = and distance = . Also, . We also need to consider distances in matrices.
-
Distances in Matrices - and . The can be directly calculated using .
-
eigenvalues, eigenvectors - A non-zero vector is an eigenvector for if there is a such that and is the eigenvalue. The characteristic polynomial of is . We do not consider the complex roots that are not real for these polynomials to calculate eigenvalues.
Spectral radius - . Then, we have the relation that and also and .
Convergent matrices - It is of particular importance to know when powers of a matrix become small, that is, when all the entries approach zero. An matrix is called convergent if for each , .
- is a convergent matrix
- for every vector .
The above statements are all equivalent.
-
Iterative techniques are not often used for smaller dimensions. We will study Jacobi and the Gauss-Seidel method.
Jacobi Method - We assume that being non-zero (as matrix must be invertible for solution) and the diagonal entries of are also non-zero. We have
Jacobi suggested that we start with an initial vector and for
The error in the iterations is given by
which gives
If , then convergence is guaranteed. If , then the condition is nothing but that of strictly diagonally dominant matrices.
Gauss-Seidel method - The idea is that once we have improved one component, we use it to improve the component of the next component and so on.
There are linear systems where Jacobi method converges but Gauss-Seidel method does not converge. If is strictly diagonally dominant, then both methods converge to the true solution.
-
Residual vector - If is an approximation to , then is the residual vector. However, it is not always true that when is small then is also small. This is because , and that represents the affine transformation of space. This phenomenon is captured as follows
For a non-singular , we have
If and
These relations work for norm too.
I think
The condition number of a non-singular matrix is
Also, . A non-singular matrix is said to be well-conditioned if is close to 1.
However, the condition number depends on the round-off errors too. The effects of finite-digit arithmetic show up in the calculation of the inverse. As the calculation of inverse is tedious, we try to calculate the condition number without the inverse. If we consider -digit arithmetic, we approximately have
One drawback is that we would have to calculate is double precision due to the above relation. The approximation for comes from . Now, . Then,
Using the above expression, we get
The only catch in the above method is that we need to calculate in -finite arithmetic.
Iterative refinement - As we had defined , in general, is more accurate. This is called as iterative improvement. If the process is applied using -digit arithmetic and if , then after iterations, we have approximately correct digits. When , increased precision must be used.
-
Approximations for eigenvalues
Gerschgorin theorem - We define discs . Then, all eigenvalues of are contained in the union of all the disks . The union of any of the disk that do not intersect the remaining disks contains precisely of the eigenvalues including the multiplicity. From this theorem, we get that strictly diagonally dominant matrices are invertible. This is also true for strictly diagonally column dominant matrices.
The above theorem provides us the initial approximations for the eigenvalues. We shall see the Power method.
Power method - We assume , and that has linearly independent eigenvectors. Choose a nonzero with a nonzero component in the dominant eigendirection. After normalizing the iterates , their direction approaches the dominant eigenvector, and the dominant eigenvalue can be estimated. (Think of vector space transformations geometrically).
If , we get
for high values of .
Sometimes, may not have the component of . We choose a vector such that this is not the case.
If all eigenvalues are nonzero, then is invertible. Applying the power method to can estimate the eigenvalue of with smallest magnitude.
Sometimes, and we’ll converge to 0. On the other hand, if it is more than 1, the limit will shoot to infinity. To take care of these, we scale , so that it is finite and non-zero.
Firstly, we choose such that and choose a component of such that . Following this, we scale each subsequent value as follows - Let and .
Now, we choose to be the least integer with and define by
Then, in general,
Now, .
To find other eigenvalues, we use Gram-Schmidt orthonormalisation.