Automata Theory
Contents
- Overview
- Chomsky Hierarchy
- Regular Expressions
- Representation of Push-Down Automata
- Non-determinism
- Non-determinism
- Properties of Languages
- Regular Expressions
- RE ≡\equiv≡ NFA-ϵ\epsilonϵ
- Decision Properties
- Pumping Lemma
- NFA ≡\equiv≡ DFA
- DFA Minimization
- Context-Free Grammar
- Grammars
- Push Down Automatons
- Simplifying grammars
- Pumping Lemma for CFG
- Ogden’s Lemma
- Closure properties
- Pushdown Automata
- Greibach Normal Form
- Equivalence of PDA and CFG
- Ogden’s Lemma revisited
- Closure properties of CFLs
- Decision properties of CFLs
- Additional closure properties of CFLs
- CYK algorithm
- Satan-Cantor Game
- Enumerability in Languages
- Turing Machines
- Definitions from set theory
- Dovetailing
- Cantor’s diagonalization
- Turing Machines (2)
- Type-0 Grammars
- Recursive Function Theory
- Limitations of primitive recursion
- Partial Recursive functions
- Equational Logic
- Term-rewriting
- Encoding Turing machines
- Variants of TM
- Universal Turing Machine
- Undecidability
- Reduction Technique
- Post Correspondence Problem
- Properties of Recursive Languages
- NP-Completeness
Overview
Theory of Computation discusses what can and cannot be done with computers. Moreover, how "hard" or "easy" a given problem is. For instance, consider the problem of determining whether a given multivariate polynomial with integer coefficients has integer roots. This problem is undecidable - we cannot write a deterministic algorithm which halts in finite time that always gives the correct answer for a given polynomial. Through the course, we will explore various techniques and theorems through the course to answer questions like these.
Example. Given a language , decide whether a word is present in this language or not. We will see that such a language can be written using a DFA.
Example. Suppose we have . Can we construct a DFA for the same?
It can be shown that such a language cannot be represented using a DFA. Instead, we use an instrument known as pushdown automaton.
A pushdown automaton has a stack associated with a DFA. Every transition in the automaton describes an operation such as "push" and "pop" on the stack. A string is accepted by the automaton if the stack is empty at the end of the string. The languages accepted by such automatons are known as context-free grammar.
Example. Extending the previous example, consider the language . Turns out, a pushdown automaton cannot represent this language.
We have a Turing machine that represents the ultimate computer that can perform any computation (not all). This machine has a 'tape' associated with it along with different decisions at each section of the tape. The languages associated with these machines are known as unrestricted grammar.
These machines and the associated languages can be represented using a diagram known as Chomsky hierarchy. We will also prove that adding non-determinism affects the expressive power of PDAs but not of DFAs and TMs.
Definition. A finite state automaton is defined as a tuple , where
- is a finite non-empty set of states,
- is the alphabet with a set of symbols,
- is the state-transition function,
- is the initial state, and
- is the set of accepting states.
A language is a subset of strings over , whereas represents the set of all possible strings that can be constructed with the alphabet. The operator is known as Kleene-star operator representing or more repetitions of symbols from an alphabet.
Is the set countable?
Example. Let us consider the language we saw before. How do we write the context-free grammar for this language? We write a set of base cases and inductive rules as follows -
Example. Consider the grammar of matched parentheses. This is given by -
- is a set of non-terminals or variables,
- is the alphabet,
- is the finite set of rules, and
- is the start symbol.
The language of a given grammar is the set of all strings derivable using the rules.
Example. Consider the language . This can be represented by the unrestricted grammar as -
Homework. Write the unrestricted grammar rules for the language
Definition. An unrestricted grammar is defined as a tuple , where
- is a set of non-terminals or variables,
- is the alphabet,
- is the finite set of rules, and
- is the start symbol.
Definition. Regular expressions are defined by the following set of rules -
-
(for any ) are regular expressions.
-
If are regular expressions,
- (union),
- (concatenation)
- (Kleene star), and
- (parenthesis)
are all regular expressions.
Example. Consider . This can be represented using the regular expression .
Homework. Suppose is restricted to have only an odd number of 's. How do we write the regular expression for this language?
In general, PDAs are represented as a Finite State Machine. That is, we have an action associated with each transition. An empty stack is denoted using the symbol . That is, the stack begins with a single symbol . Each transition is represented as , where is a letter and is an action such as
- - push
- - pop
- - not sure what this is
Now, a string is rejected by the FSM in two scenarios -
- There is no transition defined at the current state for the current symbol in the string, and
- The stack is not empty, i.e. popping the stack does not yield at the end of the string input.
Chomsky Hierarchy
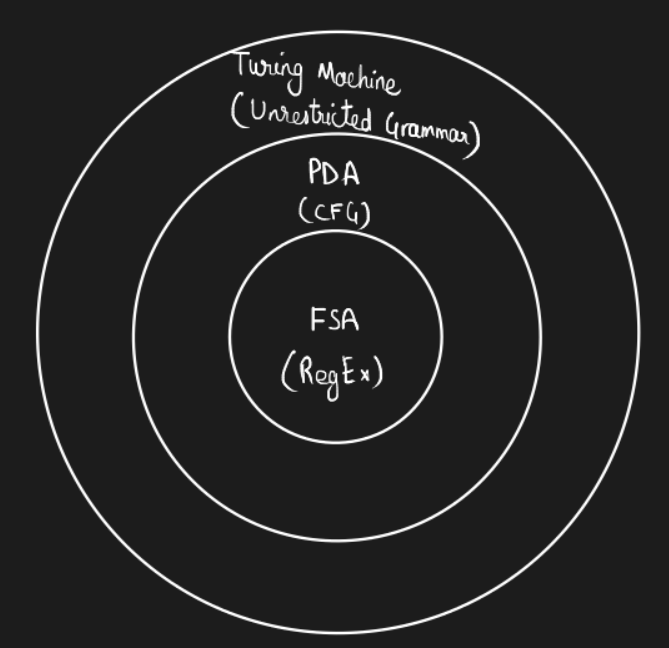
Regular Expressions
We define these languages using a base case and an inductive rule. Empty string is not the same as the empty set. The base case to be considered is ?
Inductive Rules
Lemma. If are regular expressions, then so are
- - Union
- - Concatenation
- - Kleene star
- - Parentheses
"Nothing else" is a regular expression. That is, we must use the four rules mentioned above to construct a regular expression.
The fourth rule can be used as follows - . The parentheses help us group letters from the alphabet to define the language.
Example. Construct a language with only even number of a's'. Good strings include , and bad strings include .
The automata can be easily drawn as -

How do we write a regular expression for this? Consider the expression . However this expression does not include strings that start with .
Homework. Try and fix this expression -
Example. Construct an expression for defining the language
The following automaton would work for this language -
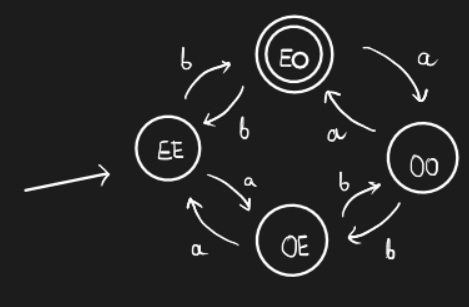
Homework. Find a regular expression for the above language.
Example. What language does the regular expression ?
It represents the language with an odd number of 's. How do we check this? Start with the base cases - It has , and it also has . Try to check the pattern and use induction.
We will soon learn how to derive relations such as "Is ?", "Is ?", "Is ?"... All we are doing right now is exploring all the topics in the course using a BFS approach.
Representation of Push-Down Automata
The bottom of the stack contains a special character that indicates the bottom of the stack. We design a Finite State Machine which knows the special characters (for bottom of the stack or other purposes) and also the top element in the stack. This FSM can pop or push on the stack to go to the next state.
Example. Represent using a FSM.
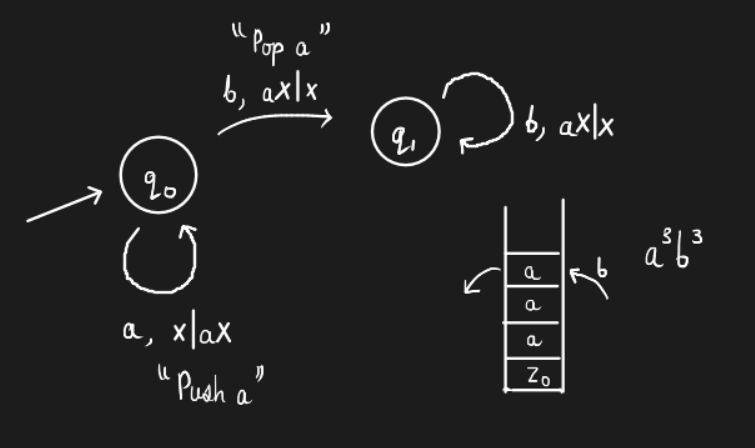
This is how a FSM is represented. A string is accepted iff the stack is empty. Note the transition from to . It says that the top of the stack must be . In case it isn't the case, the string is rejected.
In a FSM, the string is rejected due to one of the two reasons -
- No transition for the given input symbol or we reach the top stack symbol (in the case of finite length languages)
- Input is over, and the stack is not empty.
Example. Try the same for .
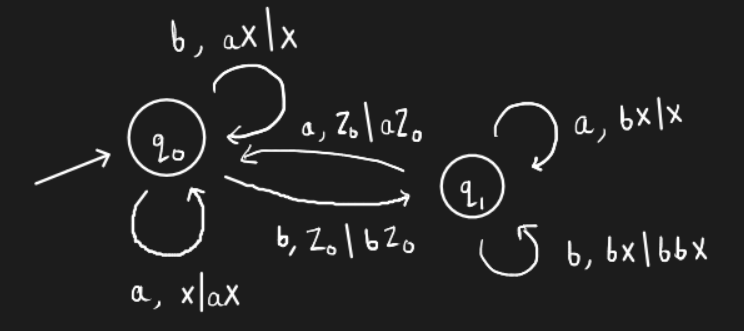
Does this work?
Non-determinism
Example. Represent . Here, "R" represents reverse. That is, this language is the language of palindromes. Here, we keep pushing and then we keep popping after a decision point. The decision point is a non-deterministic guess. If there is a correct guess, then the algorithm will work.
Example. Is composite? How do we design a non-deterministic algorithm for this problem?
- Guess for a factor
- Check if divides . If the answer is "yes" then it is composite, else repeat.
How do we reject empty strings in PDA?
Does adding accepting states in the FSM increase the representation power? Does using the special symbol in between the stack increase the representation power?
The reference textbook for this course is "Hopcroft Ullman Motwani."
Homework. Find the number of binary strings of length 10 with no two consecutive 1's.
Answer. considers bit strings starting with and considers bit strings starting with .
Therefore, there are such required strings.
Example. How do we construct an automata which captures the language of binary strings with no two consecutive 1's? We use something known as a trap state. All the bad strings will be trapped in that state, and no transition from the trap state will lead to a final state. Consider the following automaton.
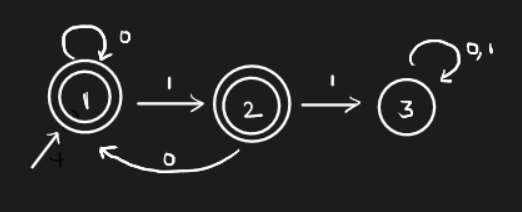
Here, the 3rd state is the trap state.
Extended transition function
is defined as
For the sake of convenience we drop the hat and use for the extended function (polymorphism).
Homework. Read the proof for showing the equivalence of language sets in DFA.
Non-determinism
Non-determinism basically refers to the procedures where we get the same output from the same input through multiple runs. In don’t care non-determinism, we get the same output with different algorithms/procedures. However, in don’t know non-determinism, a single stochastic algorithm goes through many runs (scenarios) to get the answer.
A deterministic automaton has a single choice of transition from a given state for a given symbol from the alphabet. However, in the case of a non-deterministic automata, such guarantee does not exist. The next state for a given symbol from a given state of the NFA is a set of states rather than a single state. There are two types of NFA as discussed previously.
- Don't know NFA - Guess the right choice
- Don't care NFA - All choices give the same result
One might ponder if NFAs are more expressive than DFAs. The answer is surprisingly no. Non-determinism can be introduced to an automaton in two ways -
- Choice of subset of states for each transition
- -transitions
Example. Construct an automaton to represent the language whose alphabet is
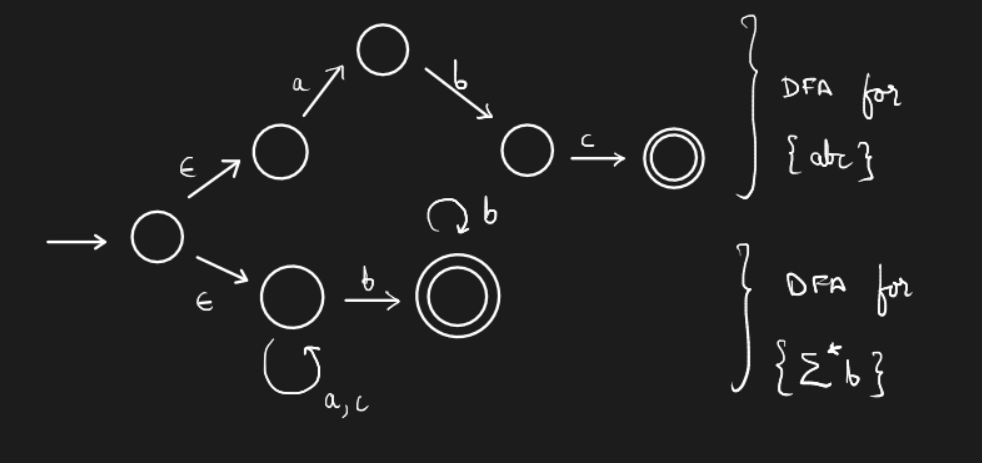
Note. We have introduced -transitions in this automaton.
As we shall see later in the course, the three models - DFA, NFA, and NFA with -transitions; are all equivalent in terms of expressive power.
Properties of Languages
We mainly check two properties of languages - decision and closure.
-
Decision - Is ? (Membership Problem) - decidable for regular languages.
Decidable problems - Problems for which we can write a sound algorithm which halts in finite time.
We can also consider problems like - Given and , Is ? or ?
Is ? Is finite? Is finite and has an even number of strings? We can also ask questions about the DFA - Can be accepted by a DFA with states (minimalism)?
Example. Can we build a DFA whose language is with less than 7 states? Turns out, the answer is no.
Finally, we can ask a very difficult question such as - Show cannot be accepted by any DFA. The technique for solving such a question is known as the Pumping Lemma. This lemma is based on the Pigeonhole principle.
-
Closure - closure using Union, Intersection, Kleene Star, and Concatenation. The question we ask is if belong to class , then does belong to ?
We plan to show the equivalence of the following models -
- DFAs
- NFAs
- NFA-
- Regular Expressions
Homework. Draw a DFA for the language where is followed by even number of s and is followed by odd number of s.
Regular Expressions
They are defined using base cases and inductive cases. Before we discuss this, we define closed-world assumption. It is the presumption that a statement that is true is also known to be true. Therefore, conversely, what is not currently known to be true, is false. More info regarding this topic can be found here. The base cases for regular expressions are given as follows.
The inductive cases are
RE NFA-
To begin with, we convert the base cases of regular expressions to NFA-s. Here are the automatons
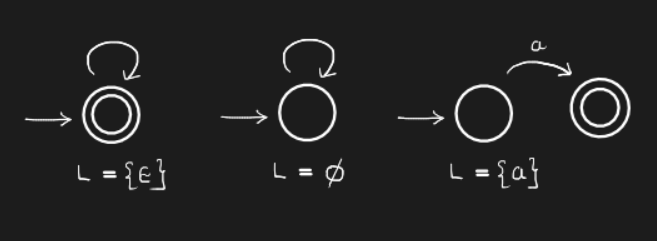
Now, for the inductive cases -
-
For union of and , consider the NFAs of both languages. Create a new start state and final state . Connect to the start states of both NFAs with transitions and the final states of both NFAs to with the same transitions.
How do we prove that this construction represents the union?
-
For concatenation of and , connect all the final states of ’s NFA to all the start states of ’s NFA using transitions.
-
For , connect all the final states of the NFA to the start states of the NFA using transitions. However, this does not accept . Fix it. Think.
Decision Properties
Membership Problem
Does ? How do we show that this problem is decidable? The algorithm is well-known.
Emptiness Problem
Is ? This problem can be solved using reachability in graphs. One can check if the final states are reachable from the start state. It can be achieved using fixed point. This method is essentially propagating the frontier from the start state. We add neighbors of all the states in the current frontier and keep expanding it. We do this until our frontier does not change. This frontier is the fixed point.
Infiniteness Problem
Is finite? We need to search for a loop in the graph to answer this question. Suppose our DFA has states. If the DFA accepts a string whose length is greater than or equal to , then a state has to repeat while forming this string. This observation is a result of the Pigeonhole principle.
This check is both necessary and sufficient. If a language is infinite, then it means that it has a string of length greater than . How are we going to use this property to check the infiniteness of the language? Is there a decidable algorithm?
Claim. If there is a string of length in , then there is a string of length between and . Think about the proof. Clue. You can use at the most self loops.
It is sufficient to test for the membership of all strings of length between and .
Pumping Lemma
Problem. Show that is not regular.
We use proof by contradiction. Assume that a with states accepts .
Theorem. Pumping Lemma. For every regular language , there exists an integer , called the pumping length, where every string of length can be written as where
Let us understand this by proving is not regular using contradiction. Assume there is a with states that accepts .
Now, consider . Since , write and with , , and . Pumping down with gives , contradicting the pumping lemma.
Homework. Prove that the language with equal number of ‘s and ’s is not regular.
The idea is to use closure properties.
Homework. Prove the pumping lemma.
Answer. Consider a DFA with states, and a word such that belongs to . Now, let (0 - indexed) be the sequence of states traversed by . The state is an accepting state as . Also, there exist such that as there are only states in the DFA (Pigeonhole principle). Now, define the string formed by as , the one formed by as y, and that formed by as . We have . Also, as and as .
Since , we can pump the string as many times as we wish by traversing cycle . Now, since , the string formed by the sequence () also belongs to . This word is equivalent to .
NFA DFA
We convert a NFA to DFA using subset construction. That is, if is the set of states in the NFA, then will the set of states in the DFA. Initially, we construct the start states using the subset of start states in the NFA. Then, we build the following states in the DFA by tracing all the states reached by each character in the NFA into a single subset. If any of the subset consists of a final state, then that subset state is made into a final state in the DFA.
This equivalence can also be extended to show the equivalence of NFA- and .
DFA Minimization
All DFAs with minimal number of states are isomorphic.
Distinguishable states
Consider a DFA . States are said to be distinguishable iff there exists a word such that and or vice versa.
One can merge indistinguishable states to minimize a DFA.
Context-Free Grammar
Let us try to write the grammar for the language . Consider the following rules
In general, union is straightforward to write in CFG due to rules like rule 1. However, there is an ambiguity in the above rules. For example, the word can be generated using different derivations. We’ll discuss this later in the course.
As we discussed before, a context free grammar is defined by . A string is accepted by the grammar if and . That is, the rules must be able to derive .
A one-step derivation is given by if and .
Consider the set of rules for defining arithmetic expressions. The language is defined over .
Now, for an expression such , we can give a left-most derivation or a right-most derivation. A precedence order removes ambiguities in the derivation. In programming languages, a parser removes these ambiguities using some conventions.
Homework. Try and write the set of rules for the language which consists of s and s such that every string has twice the number of s as that of s.
Answer. We try to write the rules for equal number of a’s and b’s, and try to extend them.
Does this work?
Note. is finite.
We had seen the CFG for the language . How can one prove that the rules represent that language? That is, how do we know that the rules generate all the strings in the language and no other strings?
Consider the language we saw in the previous lecture - strings with equal number of a’s and b’s. The possible set of rules are -
The thinking is as follows -
- generates strings with equal number of a’s and b’s. generates strings with one more b than a’s, and similarly for .
- To write the inductive cases of , we consider strings starting with both a and b. Inductive cases for are also constructed similarly.
Another possible set of rules are -
These rules are the minimized set of the rules I wrote for the hw in the last lecture.
Grammars
We can write grammars in canonical forms. A grammar is said to be in Chomsky normal form if the rules are of the form
Claim. Any grammar () can be converted to an equivalent Chomsky Normal form.
Another canonical form of grammar is Greibach normal form. The rules are of the form
Each non-terminal converts to a terminal followed by a symbol in . Similar to the Chomsky form, every grammar can be converted to the Greibach normal form.
Push Down Automatons
Consider the language .
Aside. Try writing the Chomsky normal form rules for the above language.
The pushdown automaton for this language is given by -
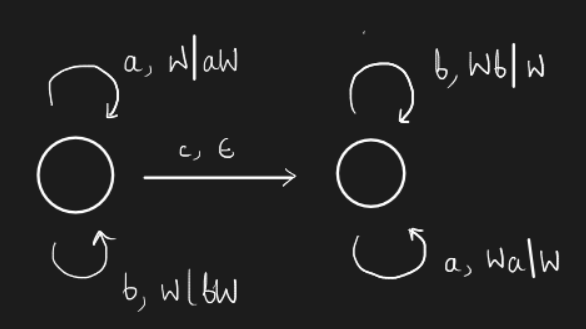
How do we take a grammar and produce the normal form of the grammar? We shall learn techniques such as eliminating useless symbols, elimination epsilon and unit productions. These will be used to get the designable form of the grammar that can also be used to show languages which are context-free using the pumping lemma.
The notation is used to denote that can be derived from in steps. The over the arrow represents the derivative closure of the rules.
Grammars are equivalent iff . For example, we have seen two grammars for the language , and they are both equivalent.
Derivation trees
- Trees whose all roots are labeled.
- The root of the tree is labeled with the start symbol of the grammar .
- Suppose A is the label of some internal node, then A has a children iff .
- can only be the label of leaf nodes.
Derivations
Grammars with multiple derivation trees are ambiguous. Are there languages for which any grammar is ambiguous? Such languages are called as inherently ambiguous.
Homework. Find examples of inherently ambiguous grammars.
Simplifying grammars
Definition. A variable is productive in iff for some .
Definition. A variable is reachable from the start symbol of if for some .
We useful variable is productive and reachable. These are necessary conditions but not sufficient. For example, consider the following grammar.
S -> AB
A -> c
Here, is useless even if it is productive and reachable.
Definition. A variable is useless if there is no derivation tree that gives from with as the label of some internal node.
Fixed point algorithm
The idea is to find a monotonic algorithm which gives us the set of useful symbols at the fixed point of the underlying function.
Firstly, let us try this for productive variables. We propose the following algorithm.
For example, consider the grammar
S -> AB | AA
A -> a
B -> bB
-- The algorithm
P_o = \phi
P_1 = {A} // Rule 2
P_2 = {A, S} // Rule 1
P_3 = {A, S}
Therefore, the symbols are productive in the above grammar. We propose a similar algorithm for reachable states in the grammar.
Definition. A nullable symbol is a symbol which can derive . These symbols can be eliminated.
Definition. A unit production is a rule of the form where .
We shall continue discussing simplifying grammars. As an initial step, we can get rid of symbols which are either unreachable or unproductive. However, the order in which we check productivity and reachability affects how the grammar is simplified. For example, consider the grammar
S -> a
S -> AB
A -> a
Now, if we eliminate unreachable symbols first (that is none), and then eliminate unproductive symbols (), we get
S -> a
A -> a
Notice that the above simplified grammar has a redundant rule. However, if we check for productivity ( is eliminated) and then reachability ( is unreachable), we get
S -> aClaim. Eliminating unproductive symbols followed by unreachable symbols gives a grammar without any useless variables.
Homework. Prove the above claim.
-productions
Suppose is a CFG such that has , then can be generated by a CFG which has no -productions (rules of the form ).
Nullable symbols
is nullable if .
How do we remove nullable symbols? We can’t just take out a rule of the form as it may make unproductive. The way to go about this is to replace each rule of the form to where
However, one must be cautious about replacing all the symbols by and also about recursive rules. For instance, consider the following grammar
Now, is nullable but we can’t replace by simply. We also need to have the rule in place for recursion. Basically, for each rule of the form , we need to have all the rules of the form where spans over all subsets of .
Unit Productions
To remove unit productions, let us assume that there are no -productions and useless symbols. Now, we need to find all pairs such that . Once we find such pairs, we can try and eliminate the unit symbols themselves, or solely the rules.
Let us take the following grammar for
and
To convert the grammar into Chomsky normal form, we do approximately the following - we replace each rule of the form with and . We keep repeating this until there is only a single terminal symbol on the rhs, or two non-terminals.
Consider a grammar in Chomsky form. The derivation tree will consist of nodes with either 2 children (), 1 child () or leaf nodes.
Let the longest path in the derivation tree be . Then, the upper bound on the length of the word formed is and lower bound is . Note. The variables from can repeat across a path.
Pumping Lemma for CFG
For any CFL , the language has a Chomsky Normal form grammar.
Theorem. Pumping Lemma For every CFL , there is a such that for all strings with , there are strings such that and
- for all , , .
It is easy to show is not a CFL using the above lemma.
Proof of the lemma
Let and take . If and , then its derivation tree has a path with at least variable nodes. By the pigeonhole principle, a variable repeats on this path.
Now, consider the path .
- It is easy to the see that the word formed by the subtree below the first has length .
- Also, as there are 2 s in the path, the number of letters in the “left” subtree and “right” subtree would be greater than 1.
- These “left” and “right” subtrees can be derived an arbitrary number of times as can be derived from .
Note. To draw some more intuition, call the subtree formed by the first as , and the subtree formed by the second as . We shall label the word formed by as , and the word labeled by as . Now, . Think. The “left” and “right” subtree in the above explanation together are formed by the set .
Homework. Show that the following languages cannot be represented by CFG.
We shall see that 2 stacks PDA is the most expressive Turing machine.
Can’t there be useless symbols in normal forms? yes ->
Ogden’s Lemma
This lemma is a generalization of pumping lemma. Consider the pumping lemma for the FSA. It basically said that some state must repeat for a string of length in the language. Ogden’s lemma talks about a similar claim for CFGs. It will be formally discussed in the next lecture.
Closure properties
The union, concatenation and Kleene closure of CFGs are also CFGs. Proof is left as a homework.
Intersection is not context-free!
Pushdown Automata
Consider the languages and . Let us build PDAs for these two models.
The stack of the PDA uses different symbols that those from . We shall denote the superset of symbols of stack by . Each transition in the PDA depends on the input symbol and the symbol on the top of the stack. These are similar to the FSA transition diagram. If both of these symbols are satisfied for the transition, we perform an action on the stack by pushing or popping symbols. Note that we can also choose to not perform any action.
We shall also use the symbol to denote ‘matching any character’ for the symbols on stack. We can also have transitions in non-deterministic PDAs. transitions basically denote ignoring input symbols.
Note. We can push multiple symbols in each transition but we can only pop one symbol in each transition.
The PDA for is given by
The PDA for is similar but we cannot express this language without non-determinism. We can’t guess where the “middle of the string” occurs without guessing. Therefore, non-deterministic PDAs are more expressive than deterministic ones.
Remember that the non-deterministic PDA accepts a string if there is at least one run that accepts it.
Formal definition of PDA
A Pushdown automata is formally given by the 7 element tuple where
- is the set of stack symbols
- is a special symbol denoting the bottom of the stack
- is the set of final states of the automata
- where is an action performed on the transition.
A string is accepted if one of the runs ends with an empty stack or at a final state. That is, . In the following lectures, we shall prove DPDA NPDA, ‘accepting by empty stack’ ‘accepting by final state’ and PDA (NPDA) CFG.
We define a move or an arrow as a transition in the PDA.
Instantaneous Description refers to the property of defining a system using a single number. In case of a PDA, the description is given by a numerical representation of (Current string, Remaining input tape, Stack content). These values, that constitute the dynamic information of a PDA, keep changing during moves. The notation denotes a single transition in the PDA. The notation is a sequence of 0 or more moves.
We have seen the accept criteria in the last lecture. We will show that a PDA built on the final state accept criteria has an equivalent PDA built on the empty state accept criteria.
Greibach Normal Form
CFGs of the form .
Note. in the above expression consists of non-terminals only!
What are the challenges involved in converting a grammar to a Greibach normal form? It involves the following steps.
Elimination of productions
Suppose we want to remove the rule and keep the language of the CFG same. Then, we consider all rules of the form and replace each of them by . After doing this, we can delete the initial production involving .
Left Recursion
Suppose we have rules of the form which we wish to remove. Now, there would be other rules involving of the form .
Now, we define a new variable . Then, we write rules of the form and . We can then remove all the left-recursive productions of . Basically, we have replaced left-recursion rules with right-recursion rules.
Ordering of Variables
Simplify the variables in one order? Wasn’t taught?
Equivalence of PDA and CFG
Given any CFG , we convert it into Greibach normal form. Then, we choose the non-terminals as the stack symbols. The initial symbol in the grammar is taken as the top symbol of the stack initially. For each rule we write the transition . We start with a single state in the DFA, and write all the rules on this state. Through this intuition, we have shown that every CFG has a corresponding PDA. Then, we need to show that every PDA has a corresponding CFG.
To show that CFG PDA, we need to show the equivalence of a language in both directions. That is, for every string accepted by the CFG, we need to show that the PDA also accepts it and vice versa. Note that we also have to prove PDA CFG.
Ogden’s Lemma revisited
Suppose we had to prove the language is not CFG. Can we do this using pumping lemma? No. Think.
We do this using Ogden’s lemma which goes something like this. You can give a such that . Now, we can mark positions by choosing a subset of ’s. Then, the from the pumping lemma must have at most marked positions and has at least one marked position. This is a stronger condition as compared to the pumping lemma.
Homework. Show that is not context-free using Ogden’s lemma.
Closure properties of CFLs
- Union - regular? Yes. Add a rule .
- Kleene closure - regular? Yes. Add a rule .
- Concatenation - regular? Yes. Add a rule .
- Intersection - Consider the example and . Both of them are context free but their intersection is not.
- Complement - Easy to show from intersection.
Decision properties of CFLs
Is the language empty?
This is easy to check. Remove useless symbols and show that is useful.
Is the language finite?
Consider the Chomsky normal form of the grammar. Draw a graph corresponding to the grammar such that every node has a single edge directed to a terminal or two edges directed to non-terminals.
Claim. If the graph has a cycle, then the language formed by the grammar is infinite. This is intuitive.
We can find cycles using DFS simply.We can derive more efficient methods which is not the goal of this course.
Does a string belong to the language?
The first approach is the following. Get the Greibach form of the grammar. Now, for each letter in the string check whether there are rules of the form . We consider the values of all such s and continue parsing the rest of the input string. Therefore, at each letter in the string we limit the number of possible derivations. If we reach the end of the string without running out of possible derivations at each letter, then the string belongs to the language. Remember that we will start with the start symbol for the beginning of the string.
However, we can see that this method is not very efficient. We shall see the CYK algorithm which works in .
Additional closure properties of CFLs
-
, where is a regular language, is also context-free.
How do we show that is not context free? It can be shown via pumping lemma which is complicated. However, it is very easy to prove it using the above property.
How do we prove the closure property? Consider a for and for . Now, we construct a ‘product’ PDA similar to what we did in NFAs. We use the ‘final state’ accept PDA for the purpose. The final states would be . It is easy to see that we can get the required property.
CYK algorithm
The Cocke-Younger-Kasami algorithm can be used to check if a string belongs to .
Suppose there is a whose membership we need to check. We consider subproblems of the form: Is derivable from any non-terminal in the grammar? Then, finally, we need to answer is can be derived from .
We consider the Chomsky normal form of the grammar for this algorithm. All strings of the form can be checked easily. For each we store all the non-terminals that can derive it. Now, the recursion for all is given by
See the following example using the CYK algorithm.
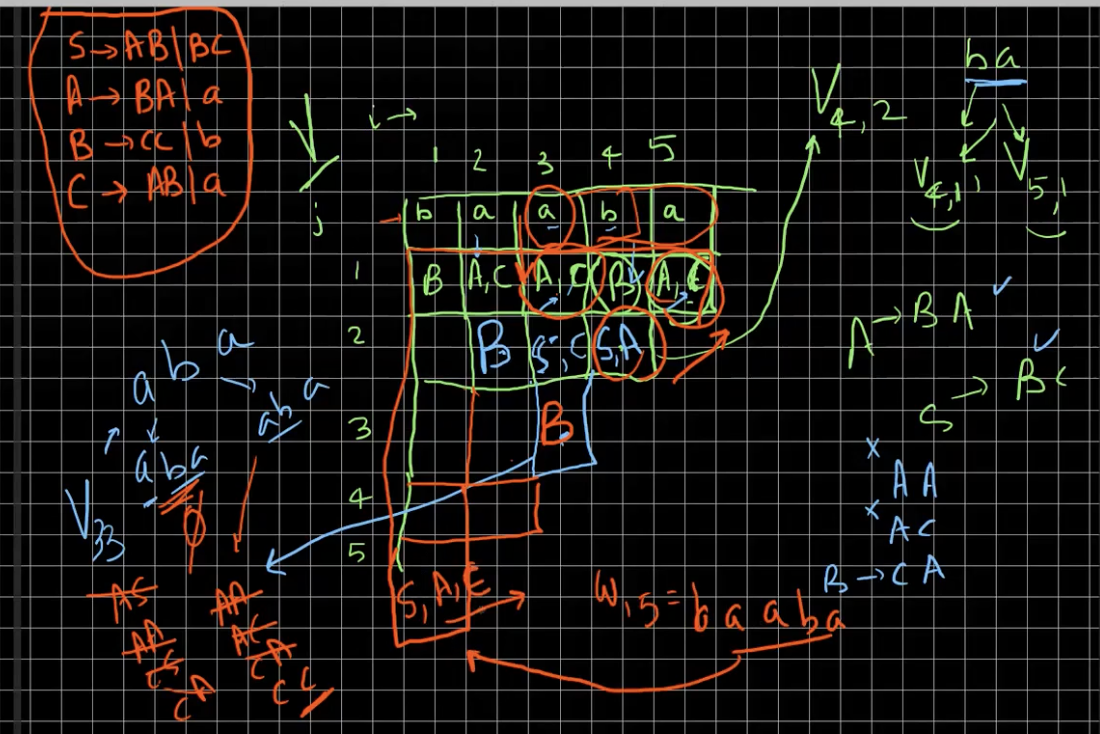
It is easy to see that this algorithm takes .
closure
We define closure for a state in a DFA as all the states that can reach via transitions. Then, to remove all the transitions from , we add a transition corresponding to all transitions from to each of the states in the closure of . Also, if any state in the closure of is final, then can also be made as a final state.
Note. Minimal DFAs need not be unique. They are isomorphic.
Satan-Cantor Game
The game goes like this. Satan chooses a random natural number and asks Cantor to guess the number. Cantor gets a chance to guess once on each day. If Cantor guesses the right number, then he can go to heaven. Does Cantor have a strategy that will guarantee him going to heaven? Yes, Cantor can choose numbers in the sequence and eventually it is guaranteed that Cantor chooses the correct number.
Suppose, Satan changes the game by choosing a random integer. Does Cantor have a strategy then? Yes, choose numbers of the form . Now, suppose Satan chooses a pair of integers, then how do we get a strategy? We can order the points based on the distance from the origin in the 2D Cartesian plane (Cantor’s pairing function). Similarly, a tuple of integers is also enumerable.
Can we give a set for Satan such that the elements are not enumerable? What if Satan chooses where is not known to Cantor. Can Cantor win in this case? Yes. Proof is homework.
Satan can choose the set of real numbers, and in that scenario Cantor would not be able to win. The key idea here is Cantor’s diagonalization argument.
Also, look up Kolmogorov complexity. Enumerability Countability.
Enumerability in Languages
A language which is finite will be regular, and we can build an FSA for it. How about infinite languages? CFLs can represent a subset of these languages.
If we categorise the infinite languages as languages which are recursively enumerable and uncountable. Can we build models for recursively enumerable languages?
Turing Machines
Turing wanted to build a machine that could recognize any enumerable language. The inspiration is drawn from the recursive function theory developed by Alonzo Church. There are other people who developed Type-0 grammars which are similar to CFGs but the left hand side of the rules can consist of a string composed of terminals and non-terminals making it context-dependent.
Church and Turing came up with a thesis, and they proposed that Church’s theory and Turing’s machine can be used to compute any effectively computable function.
Aside. Aren’t all languages enumerable with alphabet being a finite set?
“Is empty?” is a decidable problem. However, “Is the complement of empty?” is not decidable! This property was proven by Godel.
We shall now introduce the notion of Turing machines. Instead of a stack, we have an input tape with a fixed left end. A string is written in the tape with each letter being in a cell of the tape. The machine also involves a control which is essentially a FSM that takes the input from the tape, and performs actions on it. Basically, in PDAs, we could only see the top of the stack, but here we are able to freely traverse over the tape.
Definitions from set theory
Definition. Enumerable of a set refers to the property of being able to define a one-to-one correspondence from the elements of the set to positive integers.
Definition. In computability theory, a set of natural numbers is called computably enumerable, recursively enumerable, semi-decidable, partially decidable, listable, provable or Turing-recognisable if
- there is an algorithm such that the set of input numbers for which the algorithm halts is exactly .
- or equivalently, there is an algorithm that enumerates the members of . That means that its output is simply a list of all the members of . If is infinite, this algorithm will run forever.
Dovetailing
In the Satan-Cantor game, the idea was to enumerate all possible answers “fairly”.
Let us consider the scenario where Satan chooses a tuple of integers where is unknown. How do we enumerate this set? We use dovetailing for the same. Consider the tuple . For one such given tuple, we will enumerate all -tuples with distance from origin being less than . The idea is that we are balancing the enumeration across two dimensions, and , together.
Cantor’s diagonalization
How is the above set different from the power set of natural numbers? Let us consider the question in terms of languages. Consider a language with a finite . is enumerable (). Now, is the set of all languages enumerable? We know that .
We shall use contradiction to show that the set is not enumerable. Consider the following table -
| 1 | 0 | ||
| 1 | 1 | ||
The table consists of all the languages (assuming they are enumerable) with the respective strings in the language tagged as 1. Define the language . We then have a contradiction that such that for any .
Claim. The state of every computer can be encoded as a single number.
Turing Machines (2)
The machine can do the following things
- Replace the symbols on the tape by symbols in where . is a blank symbol to denote an empty cell
- Move left or right by one step
- Go to the next state
So, the labels on the transitions of the FSM are of the form where and . It means that the symbol in the cell is replaced by the symbol . The machine has to definitely move left or right in each transition. A “run” starts from the first cell and the state in the FSM. As an example, we consider the following FSM for the language .
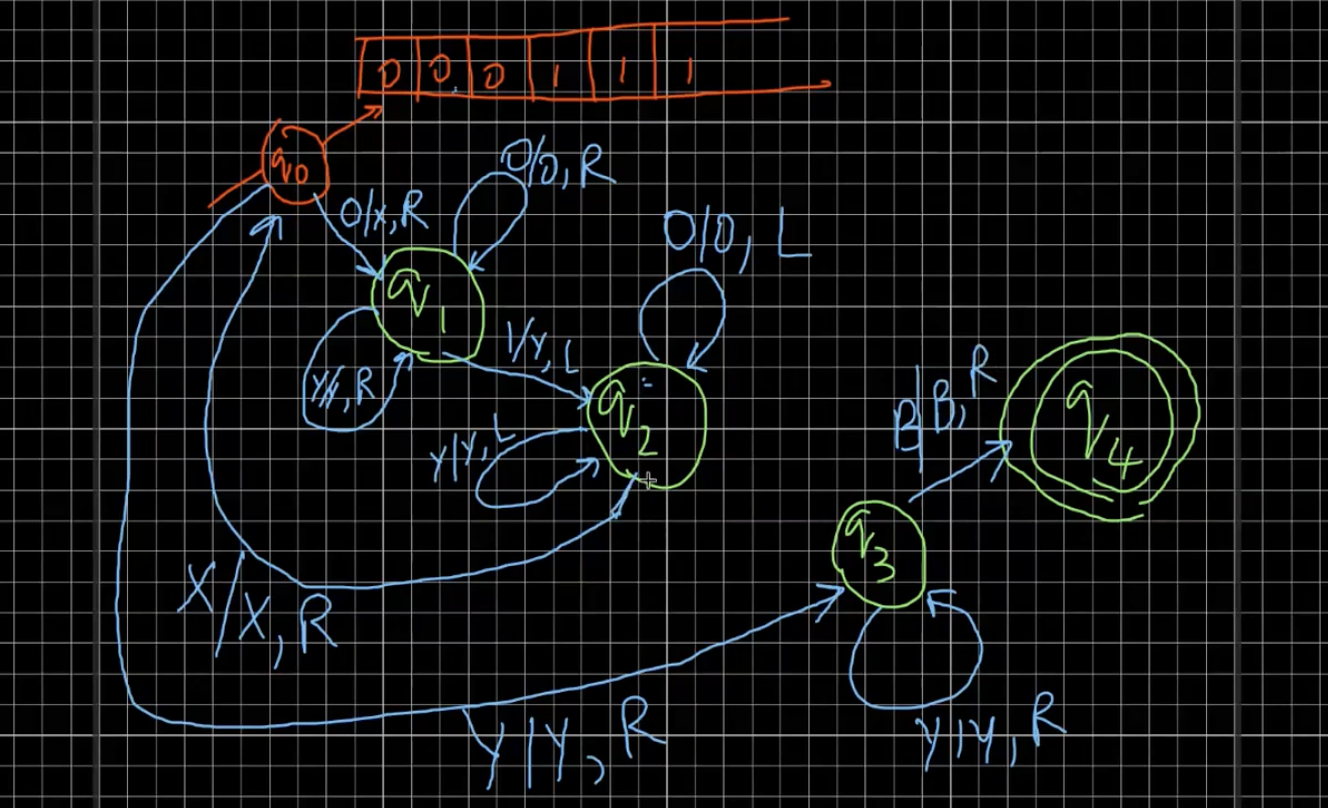
TODO Draw the above diagram again.
In a Turing machine, we halt when there is no move possible.
Formally, a Turing machine is defined as where . There are many variations possible to this machine which we shall show are equivalent to this simple definition. For example, we can have multiple tapes, output tape, non-determinism, etc.
Is countable same as enumerable? Countable implies that there is a one-to-one mapping from the elements in the set to natural numbers. This definition is equivalent to that of enumerability.
A Turing machine can enumerate a language. A language is recursively enumerable if a Turing machine can enumerate it.
is enumerable but there are languages in which are not enumerable.
The theory of Turing machines was developed in the 1930s.
Consider the derivation where the machine halts. A machine halts when there is no move at any given state. If and the machine halts, then accepts .
Variations of Turing Machines
- 2-way infinite tapes
- Multi-tape heads
- Non-determinism
- Output type (write only, immutable)
Let us try and build the Turing machine for . We’ll use the following logic. In each pass, we will change 1 a, 1 b and 1 c to X, Y and Z respectively. If we have any extra a’s, b’s or c’s, then we will halt.
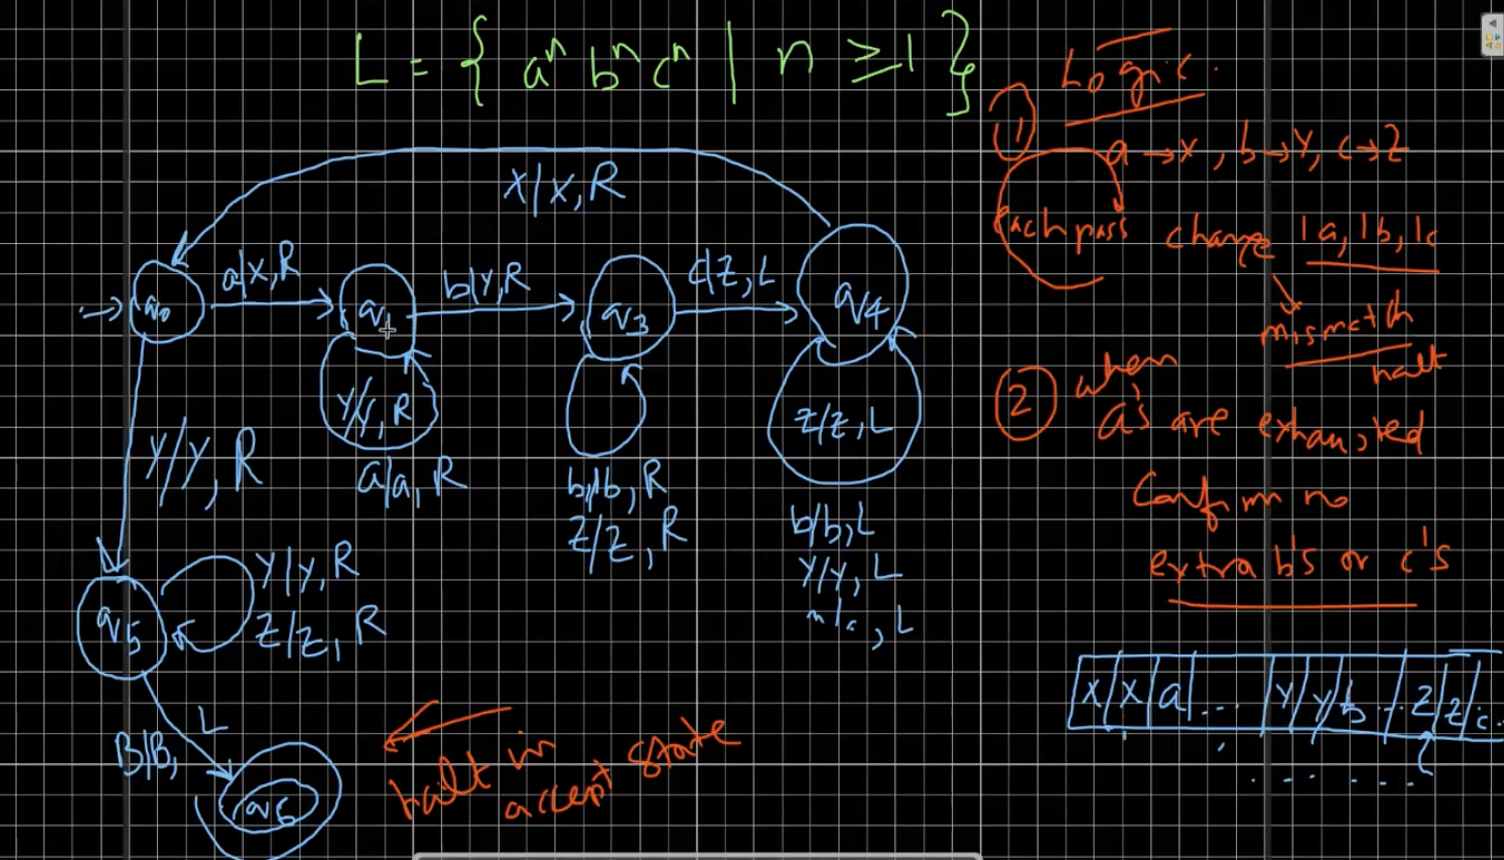
The machine is given in the above diagram.
Homework. Draw a Turing machine for the language . Hint - Think of subroutines. That is, tackle smaller problems like “Find the middle of the string”, and then match left and right.
Homework. Try
Type-0 Grammars
These are also known as Unrestricted grammars. These are essentially same as CFGs but the LHS of rules can be any string. Consider the language . The grammar can be as follows
If one notices closely, then there are a few issues with this grammar. However, it is correct considering non-determinism. That is, a terminal string derived from this grammar will be in .
Homework. Write the Type-0 grammar for
Let us go back to the language. How do we come up with a deterministic grammar? We use the idea of markers.
-
1-end marker
The problem with the above grammar is obvious. This issue is often prevented using priority rules in hierarchical grammars. Another fix for this is, adding the following set of rules
Check if this is correct
-
2-end marker
TM as a recogniser
Are the set of moves on a TM a decision procedure? A decision procedure refers to a procedure that outputs yes or no for a given input. It involves correctness and termination. No, TM does not do that. For example, consider never halting TMs. Therefore, TM is a semi-decision procedure. In order to classify TM as a decision procedure, we need to show that it halts on every input. Also, we need to show that it gives the correct answer.
TM as a “computer”
Can TM replicate any function of the form where the arguments belong to $\mathbb N$. Yes, it can be done. What should a Turing machine do when we give invalid arguments to partial functions? It should never halt. On total functions, the TM must always halt and give the correct answer. For example, we have the following TM for . Numbers and are written consecutively on the tape in unary form separated by a .
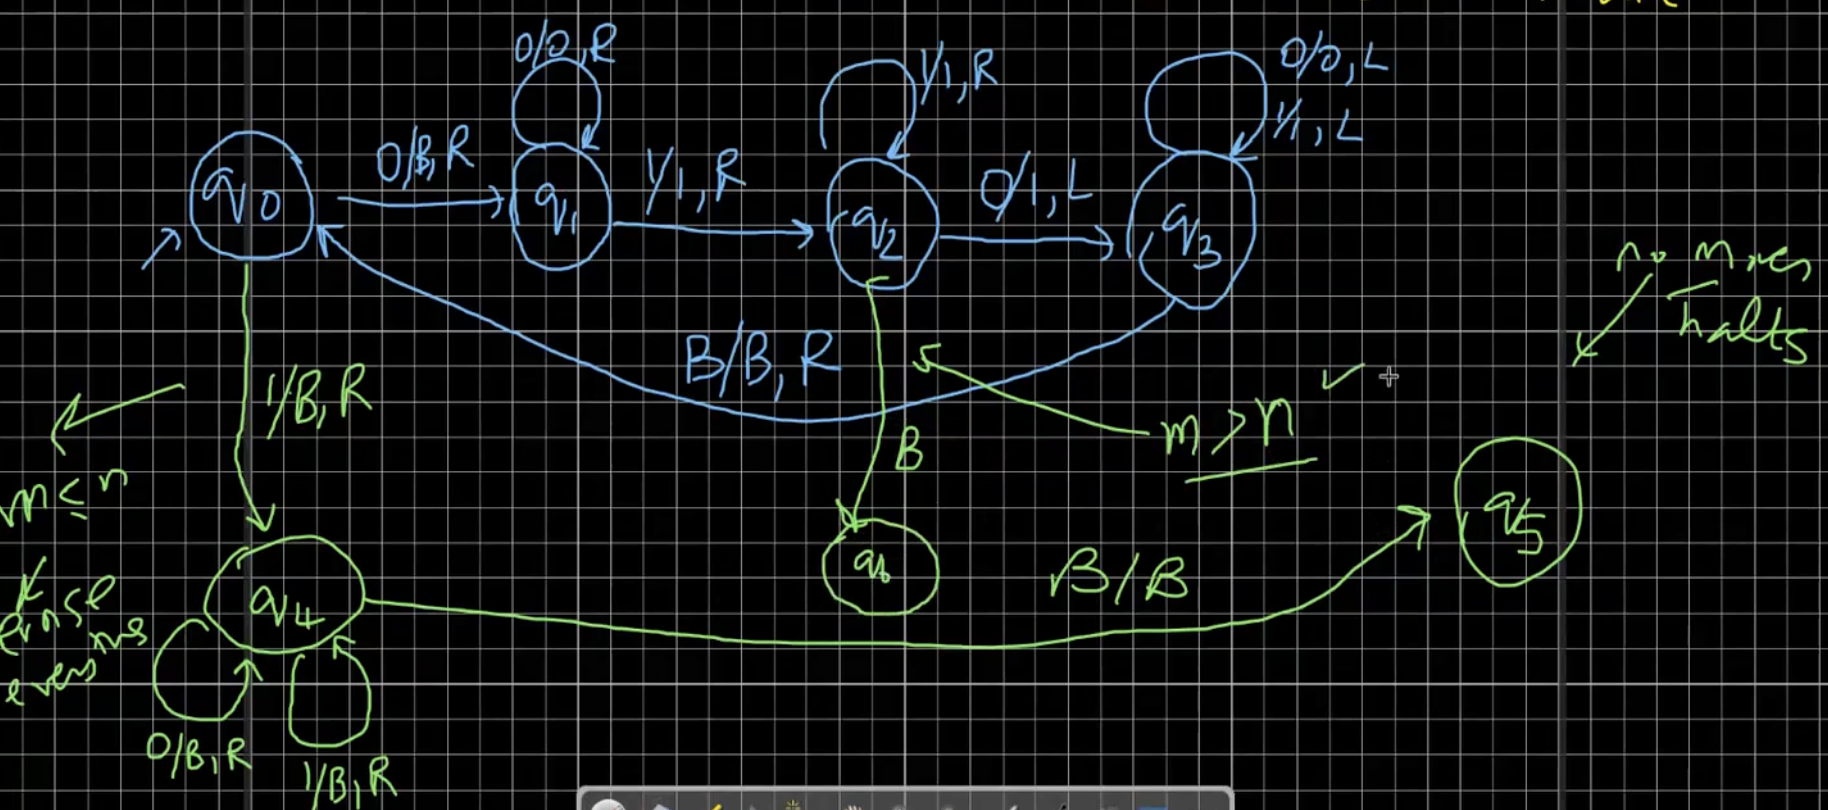
If the TM has to halt when , then we shall see that this set of TMs will only recognise recursively enumerable languages. For TMs to accept all the enumerable languages, we must allow the TM to not halt for certain inputs.
TM as an enumerator
Such TMs do not take any input. It continuously writes input on the tape and never halts. The TM prints a sequence that looks like the following for each . The machine halts if is finite, but doesn’t otherwise. is recursively enumerable iff a TM can enumerate the language.
Semi-Decision Procedure - Given for as an enumerator, construct as a recogniser for . In , we can just check if the given input is present in the list of words printed by . Now, we have come up with a semi-decision procedure based on an enumerator.
Our goal is to determine if there are any functions that cannot be computed by TMs. Or rather, are there any languages that TM cannot enumerate or recognise. Enumeration and Recognition are equivalent (hint: dovetailing).
Recursive Function Theory
Let . Any function we consider will be of the form . How do we define these functions? We start with base cases and recursion. To define these functions, we shall define some basic functions that will be used to define the others.
- Constant function - for all .
- Successor functions - .
- Projection function - for .
We move on to more primitive recursive functions.
- Composition -
Primitive recursion is given by
- Basecase -
- Recursion -
For example, the formal definition of is given by
There are functions which are not primitive recursive.
We shall see that primitive recursion is not expressive enough, Adding “minimization” to our set of rules will help us define any total function. We shall also see Equational Programming that is Turing-complete.
As we have seen earlier, we are using 3 base functions - constant, successor, and projection. Composition is depicted as .
Primitive-Recursion in layman’s terms refers to recursion using for loops. We write the functions as where are the same functions that are used in the recursive definition. For example, . The recursion must be of this form. The formal definition of is given by .
How do we write functions such as . Do we need if-then-else notion in our theory? Before we define this, let us try to define functions. We will define that for totality of the function. Then, we can define the function as . Using, we can define as .
Now, to introduce the notion of booleans, we define . We can use this function to utilise booleans. Similarly, . Using similar logic, we can implement looping and branching.
We will now see the limitations of primitive-recursion.
Limitations of primitive recursion
We have seen composition as . This concept is equivalent to passing parameters to functions in programming. To refresh the shorthand notion of primitive recursive functions, we define if-then-else as as when and otherwise. Therefore, . Using this, we define
Ackermann function
Many mathematicians tried to show that primitive recursion is not enough to represent all functions. In this pursuit, Ackermann came up with the following function
Similarly, there is a ‘91-function’ that Mc Carthy came up with. It is given as
The above function always returns for . However, it requires a lot of recursive calls for evaluating its value.
All primitive functions are total
The converse of the above statement is false. For example, the Ackermann function is not primitive. The idea is to show that any defined using primitive recursion grows slower than for some . Using Godel numbering we can count all the possible primitive recursive functions.
Partial Recursive functions
We use the idea of minimisation to define partial functions and also increase the expressive power of our definitions. We have the following definition
Notice that the first case in the above definition behaves like a while loop, as it gives the smallest value of that renders the function zero. The ‘partiality’ in the function definition comes from the fact that may never be zero.
The Church-Turing thesis states that all definable functions that can be defined using primitive recursion, minimisation, and substitution can be computed by a Turing machine. There is no proof for this yet. The set of these functions is the set of ‘all effectively computable functions’. However, there are undecidable functions that are not computable by a TM.
Equational Logic
This paradigm has the same expressive power as primitive recursion but is easier to express. To start off, we consider the function . We will define as . We write the rules as
This way of writing rules is known as Pattern matching. Similarly, is given by
In the above definition, the pattern matching is semantic and not syntactic. The syntactic pattern matching definition uses . However, note that is always assumed to be calculated in a lazy manner. That is, the condition is evaluated first and the corresponding branch is then evaluated. If the expressions in the two branches are evaluated along with the condition, then there is a chance that the computation never ends.
Also, the factorial function is given by
Another way of writing the factorial function using tail recursion is
Notice that the first definition of is very inefficient compared to the latter. The second definition does inline multiplication with the arguments carrying the answer. However, the values are pushed on to the stack in the case of the first definition. These concepts of optimisation come to great use in building compilers.
Term-rewriting
We have seen 3 computation paradigms
- Turing machine
- Type-0 grammars
- Partial recursive functions
Now, we shall see a 4th paradigm called as term rewriting.
We have terms and domains. There a few constructors involved with a domain. For example, we have for . Also, for lists we have (empty list) and (cons/pipe). We use them as follows
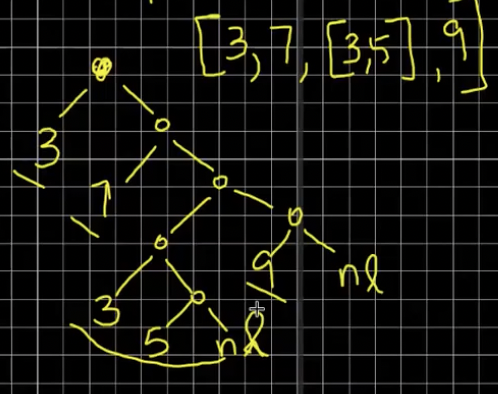
There are also constants () and function symbols/constructors (). Termination is guaranteed in normal forms. We also want unique normal form. This will ensure that a term gives a single answer with different recursions (confluence). If we get two answers, we call it ill-defined systems.
To understand this better, we shall define .
is defined as
Lists
Suppose we want to define . We then have
Similarly,
Homework. Show that
How do we sort a list of numbers?
Homework. Try quick sort and merge sort.
Termination
We have termination on due to . How about ? We use lexicographic ordering. One might think it’s not well-founded. This is because is greater than . However, it is well-founded for finite length tuples. In case of strings, the length need not be finite in lexicographic ordering. Therefore, the ordered list need not be finite.
Homework. Give an ordering rule for multi-sets
Predicates and Branching
It is easier to express these things in the term-rewriting paradigm. I’m skipping these for brevity.
Can we write , , and ? This paradigm naturally develops to Functional Programming. It’s essentially writing everything in terms of functions as we’ve been doing so far.
Logic Programming
Suppose we give the black-box the input . Can we determine ? Can we ask multiple answers in case of ? It is possible to do so in logic programming. We do this by passing parameters by unification. That is, we try to convert the parameters to look like the parameters given in the rules of . This is known as backtracking.
Term matching is don’t care non-determinism. There might be multiple possible reductions at any given situation, and all will lead to the same answer in case of well-formed normal forms. Also, all the paths should terminate.
What are the strategies for computing normal forms?
- Hybrid - Check if sub-term matches rule-by-rule
- Innermost - Many programming languages adopt this. Evaluate the “lowest” redex first.
- Outermost - This is lazy evaluation. We evaluate topmost redex first.
Redex is a sub-term where a rule can be applied.
And then, sir lost his connection :D
Aside. Write primality test function using primitive recursion.
We were discussing the definition of in the previous lecture. In terms of minimisation, we can write the definition as
Encoding Turing machines
Let us consider the example of enumerating all the finite subsets of . A subset is represented as where are the first prime numbers. Note that we need to ignore trailing zeros for this.
Can we enumerate Turing Machines? Let us try to encode a Turing Machine as a bit string. The core idea is that a Turing Machine has a finite set of states. We can encode a transition in the following way - Suppose we have the transition . Then, the bit string corresponding to this is
Here, a just acts as a separator, and every state, tape symbol and direction are encoded in unary format. A substring represents the start of a transition, followed by for the above example. This way, we can list all the transitions of the Turing Machine. All the transitions can be enclosed between a pair of substrings . Now, we just need to add the set of final states.
Instead of listing out all the final states, we can convert the Turing Machine to an equivalent TM which has a single finite state.
Homework. Prove that the above conversion can be done for any Turing Machine.
Now that we have encoded a TM, how do we enumerate the set of all TMs? We know how to enumerate bit strings based on the value and the length (ignore leading ‘s for non-ambiguity). We need out to weed out the bit strings that do not represent a valid TM.
What features are present in a bit string that represents a TM? It needs to start with , and end with . If there is a in between the above substrings, there need to be at least 4 ‘s in between with appropriate number of ’s in between. This concludes our discussion on encoding TMs.
Variants of TM
Let us consider the time of execution with a single computer and computers. Any task will have at most times speedup when done on -computers in comparison to a single computer (generally). For example, matrix multiplication can be heavily parallelised. However, tasks such as gcd calculation of numbers is inherently sequential and it is not easy to speed it up using parallel computation.
Now, we shall consider variants of TMs and show equivalence of each with the 1-way infinite tape variant.
2-way infinite tape
It is easy to see that a 2-way infinite tape can be restricted of the left movement beyond a point to simulate all the 1-way infinite tape machines.
To prove the other direction, we will consider a multi-track 1-way TM. That is, every cell will now contain 2 elements. The basic idea is that a 2-way machine of the form will be converted to .
The states in the 2-way machine will be separated based on whether the transition is on the left side of the tape or the right side. Then, based on the side, we will work on the first element in the tuple of each cell or the second element. The formal proof is left to the reader.
Multi tapes
There are multiple tapes under a single control. Therefore, each transition is represented as . One can see that all the logic boils down to the Satan-Cantor puzzle.
Again, one direction of the equivalence is straightforward. The other half involves converting a -tuple to a natural number.
Non-Determinism
The equivalence can be shown in a similar way as that of regular languages.
k-head machine
We have a single tape which has multiple heads that move independently.
Offline TM
The input tape never changes. That is, the actions are read-only.
Universal Turing Machine
The intention is to build a general purpose computer. Recollect that a Turing Machine is represented as .
Every Turing Machine has an equivalent TM
- whose alphabet is and the set of tape symbols is , and
- has a single final state.
is
- recursively enumerable - there exists a TM (recogniser) that accepts (need not halt on wrong input, think of recogniser built from enumerators).
- recursive - there is a TM that accepts which halts on all inputs.
For example, consider the language that accepts a pair of CFGs if . To show that this language is recursively enumerable, we will give a high level algorithm in terms of primitive steps that we know can be converted to a TM. We consider the following algorithm.
- Enumerate L(G_1) // enumerate w, check G_1 =>* w (CYK)
- For each w in L(G_1) check if G_2 =>* w
Now, if we generate a word and check for the word in the other grammar alternately, then the algorithm will halt if the input is acceptable. However, it is not guaranteed to halt in case of unacceptable input for this algorithm. Does that mean the language is recursively enumerable?
We need to show that we can’t construct an algorithm that halts in case of an unacceptable input. Then, we can conclusively state that the language is recursively enumerable.
In conclusion, there are language that are recursively enumerable, and languages that are not recursively enumerable. The set of recursive languages are a strict subset of the set of recursively enumerable languages.
Non-recursive language
We know that we can enumerate all TMs and all . Then, we draw a 2D infinite bit matrix A where tells whether . Now, we use the Cantor’s diagonalization argument to conclude that is not recursively enumerable. Genius proof based off Barber’s paradox.
If is not recursively enumerable, then is also not recursively enumerable. That is, show that if TM accepts , then it must also accept .
One might ponder on how we construct the table when some TM may not halt for a few inputs. The important distinction is that, we are “defining” this table conceptually and not “computing” it. The concept of dovetailing also comes to use here.
Recursively enumerable but not Recursive
The language of the Universal Turing Machine is the required example. We formally define this language as .
Equivalently, we are trying to write a Python script that takes another Python script as input along with some arguments. This script should halt when the input python script halts on the input argument, and need not halt otherwise. Basically, we are trying to build a simulator TM.
No lectures 32 and 33.
Undecidability
A language is recursive if there is a Turing Machine that halts in an accept state if and in a reject state if . It need not halt in reject states for recursively enumerable languages. The algorithms similar to the latter TMs are semi-decidable.
We were looking for languages that are not recursively enumerable and languages that are recursively enumerable but not recursive . For the latter set, we had seen the universal TM. We also have the language of “polynomials that have integer roots”. How do we show that this is recursively enumerable? The key idea lies in encoding polynomials as a number. The motivation for this language comes from Hilbert’s 10th Problem.
Another example for an undecidable problem is the Halting Problem.
Let us continue the discussion on and from the last lecture. We had constructed a matrix and showed using the diagonalization argument that there are languages that are not recursively enumerable. However, we did not address two issues
- There are multiple TMs that accept the same language - It does not matter.
- How do we fill the table? - Computation vs Definition.
Also, all the languages defined by each row in the matrix form the set of recursively enumerable languages.
We had defined as . We will show that this language is recursively enumerable by constructing a Turing Machine that accepts this language. The input tape will initially have the encoding of followed by the encoding of . Now, we use two more tapes
- One for copying
- Another tape for keeping track of the state in , starting with state 0.
Now, we give the higher level logic of .
- Validate . This can be done using a TM.
- Run step-by-step. Pick the top state from the 3rd tape, find the corresponding move from the first tape, and update the 2nd and 3rd tapes.
The last two tapes help simulate any input TM. In conclusion, we have constructed a universal TM. Therefore, the TM paradigm is powerful enough to perform self-introspection.
Note that we have still not shown is not recursive. We will use the properly of not being recursively enumerable to show this.
Let us continue the discussion on the Universal Turing Machine. The encoding of a move in a Turing Machine is . The universal TM works in 3 steps
- Decode/Validate
- Set up the tapes
- Simulate
Also, we had shown that is recursively enumerable by the construction of the universal TM. Suppose, there is a TM that halts every time for . Now, we will show that is recursive then is recursive. To do that, we will convert into an instance of .
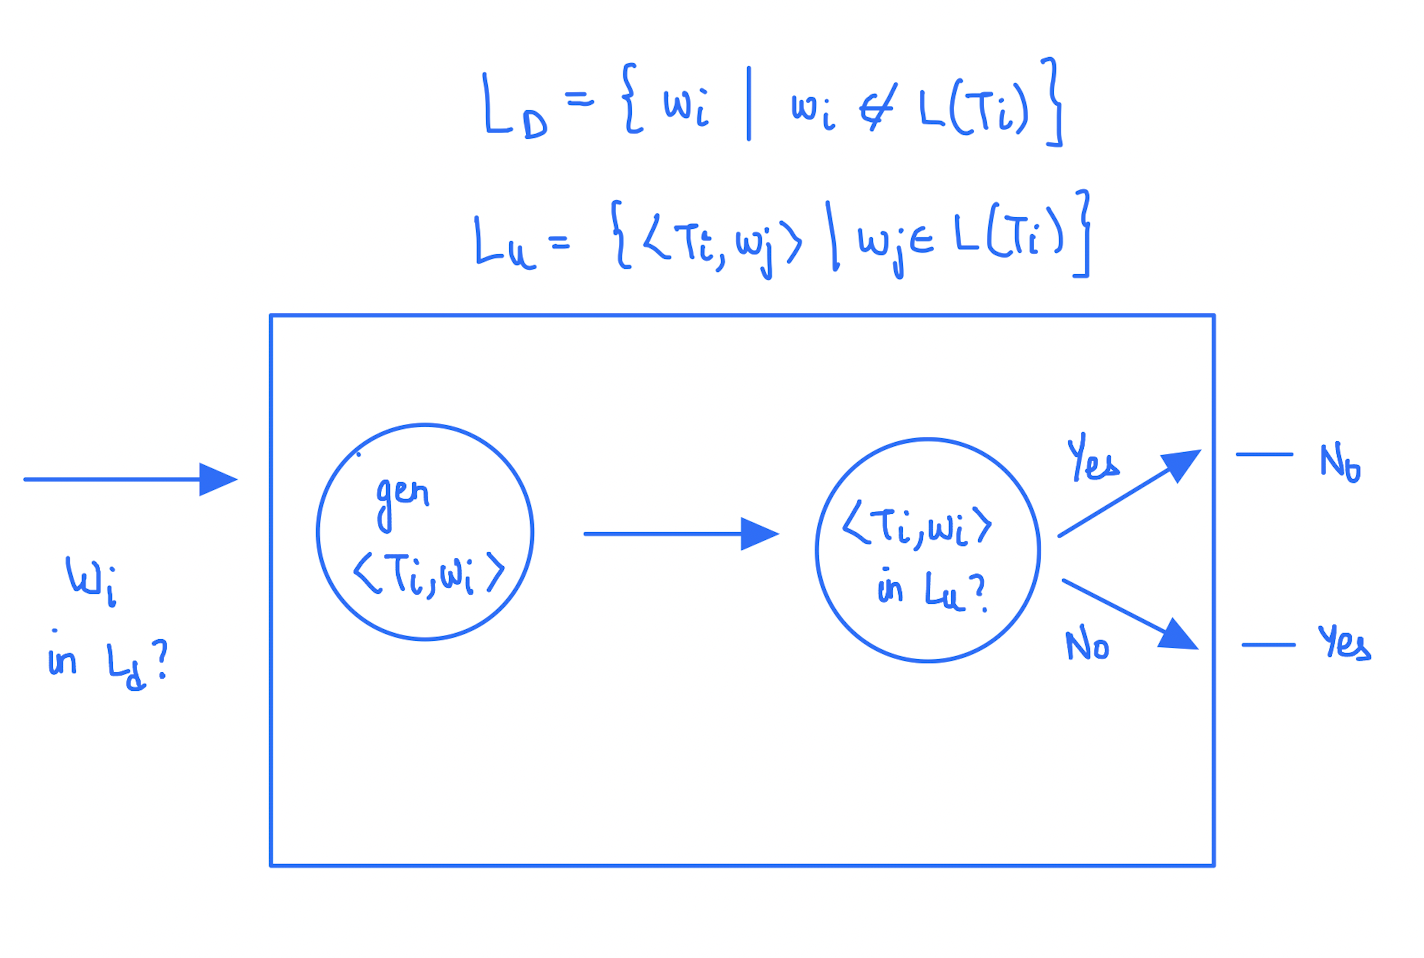
Here, we can see that we are able to answer the question by constructing a TM using the Universal TM. That is, if the Universal TM is recursive, then is also recursive. Think.
Reduction Technique
To understand this technique, consider the following two problems
- - Machine accepts at least one string
- - The language recognized by is decidable
The first language is recursively enumerable using dovetailing (words and moves being the dimensions). The second language is not recursively enumerable. To show non-recursivity, we convert or to an instance of this language. We need to try and come up with an algorithm that halts for machines with empty languages.
How do we do this?
The second problem is a little bit more difficult.
In conclusion, given a language
- To prove that it is recursive, we need to construct a TM that halts on all inputs.
- To prove that it is recursively enumerable, we just need to construct a TM that halts on good inputs. To show that it is not recursive, we need to use reductions probably.
- To prove non recursively enumerable, we need to show that we can’t construct any TM.
TM is a powerful model as it is universal (self-referential), and it has many undecidable problems. They can represent Type-0 Grammar, Partial Recursive functions, and RAM (random access mechanism).
Post Correspondence Problem
Post is a mathematician. Consider the following table
| w | x |
|---|---|
| 1 | 111 |
| 1011 | 10 |
| 10 | 0 |
Now, take the string . Can we decompose this string in terms of or ? For example, we can decompose the string as in terms of and again in terms of . These decompositions need not be unique.
So, PCP is stated as follows.
Given and a string , we need to be able to come up with decompositions and such that for .
Consider the following table.
| w | x |
|---|---|
| 10 | 101 |
| 011 | 11 |
| 101 | 011 |
Now, for any string , we will not be able to come up with decompositions that are equal for the above sets.
The reason we came up with this problem, is to show that PCP is undecidable (not recursive). That is, no TM can halt correctly on all PCP instances. However, it is recursively enumerable as we can enumerate all sequences fairly. This can be shown by a reduction of to PCP.
Let us now consider another problem - Ambiguity of CFGs. Can we build a TM that halts with a ‘yes’ if the input CFG has an ambiguity and with a ‘no’ is it does not. In an ambiguous grammar, a single word has multiple derivations in the grammar. That is, we have multiple structurally different derivation trees. Using this problem we are trying to show the importance of direction of reduction. We know that PCP is undecidable. Therefore, we need to reduce PCP to an instance of the CFG problem. That is, we’ll essentially show that is the CFG problem is decidable, then so is PCP.
PCP is essentially a pair of sets of strings. What is the grammar corresponding to these sets such that when PCP has a solution, the grammar is ambiguous and unambiguous otherwise? We introduce new symbols . We construct the following grammar
S -> Sa | Sb
Sa -> w_i Sa a_i | w_i a_i
Sb -> x_i Sb a_i | x_i a_i
It is easy to see that this grammar meets our requirements. To prove this, we need to show the proof in two directions
- If PCP has a solution, then G is ambiguous
- If G is ambiguous, then PCP has a solution. Here, we need to show that ambiguity happens only due to
SaandSb.
Why did we introduce
a?
Note. To show problem A is undecidable knowing that problem B is undecidable, we essentially show that A is a subroutine of B.
Properties of Recursive Languages
If and are both recursive, then so are
Recursively enumerable languages are closed under intersection, but not under complement.
Note. Don't get confused into thinking there are three (disjoint) kinds of sets: decidable, semi-decidable, and undecidable. There are two kinds: decidable and undecidable. Semi-decidable falls under undecidable.
NP-Completeness
Decision Problems
These are a class of problems that deal with problem instances like Fermat’s last theorem - ? We also have the law of excluded middle in decision problems - The answer is either ‘yes’ or ‘no’.
Optimisation problems can be converted to a decision problem.
Decidable Problems
We solve these problems by building a brute-force TM - generate and test method. For example, consider the problem of finding a vertex cover in a graph of size . Now, the TM will enumerate all subsets of size and check each one for vertex cover conditions.
We come up with “algorithms” for these problems and check their efficiency. Apart from time and space complexity, we also consider descriptive (Kolmogorov) complexity. It refers to the program size. In our case, it refers to the size of the TM.
Complexity Classes
Given two problems, which problem is “more difficult”? The difficulty criterion we consider is time. We define two classes of problems and .
- P is the class of (decision) problems that can be solved in “polynomial time” by a deterministic Turing Machine .
- PSPACE refers to the class of problems that use polynomial number of cells in the tape.
- NP is the class of (decision) problems that can be solved in polynomial time by non-deterministic TM. This is equivalent to guessing a solution in polynomial time followed by checking using a deterministic TM in polynomial time. The claim is that this is same as a non-deterministic TM. We shall use this technique to show that problems are in NP. That is, we’ll show that we can guess in P-time and verify in P-time.
For example, let us try to show vertex cover problem is in . Aside - A polynomial algorithm was developed in the 1980s for the problem “Is a prime number” in IITK (Manindra Agarwal).
More difficult problem
Given and , which one is more difficult? We use reduction to answer this question.
If can be converted to an instance of in polynomial time, then we have the above defined relation. That is, is at least as difficult as .
Completeness
We try to determine the most difficult problem amongst all the problems. To start off, we define that belongs to NP-complete set. This problem refers to the satisfiability of propositional logic expressions.
Every problem in can be reduced to . In some sense, is the most difficult problem. But how did we come to this conclusion without knowing all the problems in ? We can show that any non-deterministic TM can be reduced to .
We define hard problems as anything not in . There are problems that are more difficult than the ones in !
We classify decidable problems as the set of recursive languages. These problems can be further classified as
-
Deterministic TM takes only polynomial number of steps in terms of the input size to halt.
-
A non-deterministic TM takes polynomial number of steps.
-
A non-deterministic TM needs number of steps.
SAT Problem
Given a well formed formula , is satisfiable? A well formed formula is a formula that is formed via the base case (propositional variables) and inductive rules (using connectors like negation, ‘and’ and ‘or’).
This problem can be solved via brute force but that is exponential. So we now ask the following questions
- Is ?
- Is ?
We’ll answer the second question first. It is easy to construct a non-deterministic TM that solves the problem in polynomial steps. We can generate a random guess (bit string) and verify (check satisfiability) in polynomial steps. This procedure is the way to show that any problem is in .
Comparison of Problems
Let us revisit the topic of . , and where is the vertex cover problem.
To do perform the latter reduction, we construct nodes for and for each propositional variable in the clause. Then, we construct cliques out of each disjunction in the CNF. Finally, we connect each with . Now, if we can find a vertex cover of this graph with size , we get the satisfiability of the 3-CNF clause with disjunctive clauses.
- If has a satisfying assignment, take out exactly one literal with value out of each disjunctive clause and construct a VC out of the remaining literals. It can be shown that the vertex cover will have size .
- If there is a vertex cover, then we can drop at most 1 node from each disjunctive clause. Also, as the size if we can drop exactly 1 node from each clause. Assign these dropped nodes with a value of . Now, since we have a true value in each clause, the assignment satisfies the expression.
NP-Completeness
As we mentioned before, we consider or as the hardest problem. That is, for every , .
We show this by reducing non-deterministic Turing Machines to . To prove that a problem is NP-complete, we show
- That the problem lies in . This step is very important as there are problems that are more difficult than .
- Convert the 3-SAT problem (or any other known NP-complete problem) to an instance of the given problem.
We list out some problems in NP-complete set.
- 3-SAT
- Vertex Cover
- Clique in a graph
- -coloring
- Min-cut and Max-flow
- Travelling Salesman Problem
- Hamiltonian Cycle in a graph
- Partitioning of a set of numbers such that the partitions have the same sum
- Knapsack problem
The good news about -complete problems is that there are many heuristics and approximations such as LAs Vegas and Monte Carlo that work well for most of the above problems.